Prospective PhD Student Q&A – October 2, 2026

Thinking about applying to graduate school? Wonder what it’s like to pursue a PhD or research-based master’s degree? Interested in understanding relationships between technology and society? Curious about how to do research on online communities like Reddit, Wikipedia, or GNU/Linux? The Community Data Science Collective is hosting a virtual Q&A session on Friday, October 2 at 12 pm PT / 2pm CT / 3pm ET for prospective students. This session is scheduled for an hour and will be divided between a larger group session with faculty and smaller groups with current graduate students. If you would like to attend, register at this link!

This post provides a very brief rundown on the CDSC, the different universities and PhD and research master’s programs our faculty members are affiliated with, and some general ideas about what we’re looking for when we review applications.

What is the Community Data Science Collective?

The Community Data Science Collective (or CDSC) is a joint research group of (mostly quantitative) empirical social scientists and designers pursuing research about the organization of online communities, peer production, and learning and collaboration in social computing systems. We are based at Northwestern University, the University of Washington-Seattle, University of Washington-Bothell, The University of Texas at Austin, Purdue University, and a few other places. You can read more about us and our work on our research group blog and on the collective’s website/wiki.

What are these different Ph.D. programs? Why would I choose one over the other?

This year the group includes multiple faculty principal investigators (PIs) who are actively recruiting graduate students: Kaylea Champion (University of Washington in Bothell), Nathan TeBlunthuis (University of Texas at Austin), Jeremy Foote (Purdue University), Benjamin Mako Hill (University of Washington in Seattle), Aaron Shaw (Northwestern University). Each of these PIs advises PhD and/or M.S. students in graduate programs at their respective universities. We also have one faculty PI who is not currently recruiting students, but is an active member of the group: Ryan Funkhouser (University of Idaho). Our programs are each described below.

Although we often work together on research and serve as co-advisors on students’ projects, each faculty member has specific areas of expertise and interests. The reasons you might choose to apply to one of these PhD or M.S. programs or to work with a specific faculty member could include factors like your previous training, career goals, and the alignment of your specific research interests with our respective skills.

At the same time, a great thing about the CDSC is that we all collaborate and regularly co-advise students across our campuses, so applying to or attending one program does not prevent you from accessing the expertise of our whole group. But please keep in mind that our different PhD and M.S. programs have different application deadlines, requirements, and procedures!

Faculty who are actively recruiting PhD Students this year

If you are interested in applying to any of the programs, we strongly encourage you to reach out to the specific faculty in that program before submitting an application.
Nathan TeBlunthuis, Ventrait Pictures

Nathan TeBlunthuis is an Assistant Professor in the School of Information at the University of Texas at Austin in the area of social informatics. Nathan’s research focuses on analyzing ecosystems of online communities, AI tools in peer production, and methods in computational social science. His current projects continue in these areas and also draw from them all to understand how information sources achieve legitimacy in online communities. He works primarily using computational tools and big data, but also grounds his work in qualitative evidence.
Jeremy Foote

Jeremy Foote is an Assistant Professor at the Brian Lamb School of Communication at Purdue University. He is affiliated with the Organizational Communication and Media, Technology, and Society programs. Jeremy’s research focuses on how individuals decide when and in what ways to participate in online communities, how communities change the people who participate in them, and how both of those processes can help us to understand what people believe and which things become popular and influential. He and his students use multiple methods, including data science, agent-based modeling, field experiments, and interviews.
Benjamin Mako Hill, Photo by Pedro Pacheco

Benjamin Mako Hill is an Associate Professor of Communication at the University of Washington. He is also adjunct faculty at UW’s Department of Human-Centered Design and Engineering (HCDE), Computer Science and Engineering (CSE), and the Information School. Although many of Mako’s students are in the Department of Communication, he has also advised students in all three other departments—although he typically has more limited ability to admit students into those programs on his own and usually does so with a co-advisor in those departments. Mako’s research focuses on population-level studies of peer production projects, computational social science, efforts to democratize data science, and informal learning. Mako has also put together a webpage for prospective graduate students with some useful links and information.
Aaron Shaw, Nikki Ritcher Photography

Aaron Shaw is a Professor in the Department of Communication Studies at Northwestern. In terms of PhD programs, Aaron’s primary affiliations are with the Media, Technology and Society (MTS) and the Technology and Social Behavior (TSB) Ph.D. programs (please note: the TSB program is a joint degree between Communication and Computer Science). Aaron also has a courtesy appointment in the Sociology Department at Northwestern, but he has not directly supervised any Ph.D. advisees in that department (yet). Aaron studies organizing, participation, and governance in online communities, especially ones that create public information resources and digital infrastructure. Aaron’s current projects focus on comparative analysis of the organization of peer production communities, online community governance, LLM-based social science, and AI’s impacts on digital public infrastructure.

Faculty who Supervise ADMITTED M.S. and B.S. Students
Kaylea Champion

Kaylea Champion is an Assistant Professor in Computing & Software Systems at the University of Washington-Bothell. Kaylea’s research investigates how people collaborate to build digital infrastructure, including operating systems, programming languages, and information repositories. What gets made and maintained and secured—and what gets neglected? What risks do we face (including from AI and cybercriminals)? What practices lead to better outcomes? How can we work smarter and what can we stop doing? Kaylea’s work seeks to bridge the divide between research and practice, which for her means building relationships with practitioner communities, organizations, and industry to directly share research findings. If you are interested in the Computing & Software Systems graduate programs at the University of Washington – Bothell, you should register for one of the information sessions specific to these programs as well. Kaylea’s department only admits M.S. and B.S. students (MS-Cybersecurity and MS-Computer Science and Software Engineering). In addition, she is happy to support any students who are working with others in the CDSC and can serve on thesis and dissertation committees.

Other Faculty members of the CDSC
Ryan Funkhouser

Ryan Funkhouser is an Assistant Professor in the Department of Psychology and Communication at the University of Idaho. Ryan’s research focuses on communication processes for bridging ideological divides in online spaces. His work includes explorations of deliberation-focused online communities, the role of narrative in persuasion, and the mechanisms of belief change. Ryan utilizes both computational and qualitative methods to explore text data, primarily from online sources.

What do you look for in PhD applicants?

There’s no easy or singular answer to this. In general, we look for curious, intelligent people driven to develop original research projects that advance scientific and practical understanding of topics that intersect with any of our collective research interests.

To get an idea of the interests and experiences present in the group, read our respective bios and CVs (follow the links above to our personal websites). Specific skills we regularly use include consuming and producing social science and/or social computing (human-computer interaction) research; applied statistics and statistical computing; various empirical research methods; social theory and cultural studies; and more.

Formal qualifications that speak to similar skills and show up in your resume, transcripts, or work history are great, but we are much more interested in your capacity to learn, think, write, analyze, and/or code effectively than in your credentials, test scores, grades, or previous affiliations. It’s graduate school, after all, and we do not expect you to show up knowing how to do all the things already.

Intellectual creativity, persistence, and a willingness to acquire new skills and problem-solving matter a lot. We think doctoral education is less about executing tasks someone else hands you and more about learning to identify a new, important problem; develop an appropriate approach to solving it; and explain all of the above and why it matters so others can learn from you in the future. Evidence that you can or at least want to do these things is critical. Indications that you can also play well with others and would make a generous, friendly colleague are really important too.

All of this is to say, we do not have any one trait or skill set we look for in prospective students. We strive to be inclusive along every possible dimension. Each person who has joined our group has contributed unique skills and experiences, as well as personal interests. We want our future students and colleagues to do the same.

Now what?

Still not sure whether or how your interests might fit with the group? Still have questions? Still reading and just don’t want to stop? Follow the links above for more information. Feel free to email at least one of us. We are happy to answer your questions and always eager to chat.
Community Data Science Collective logo

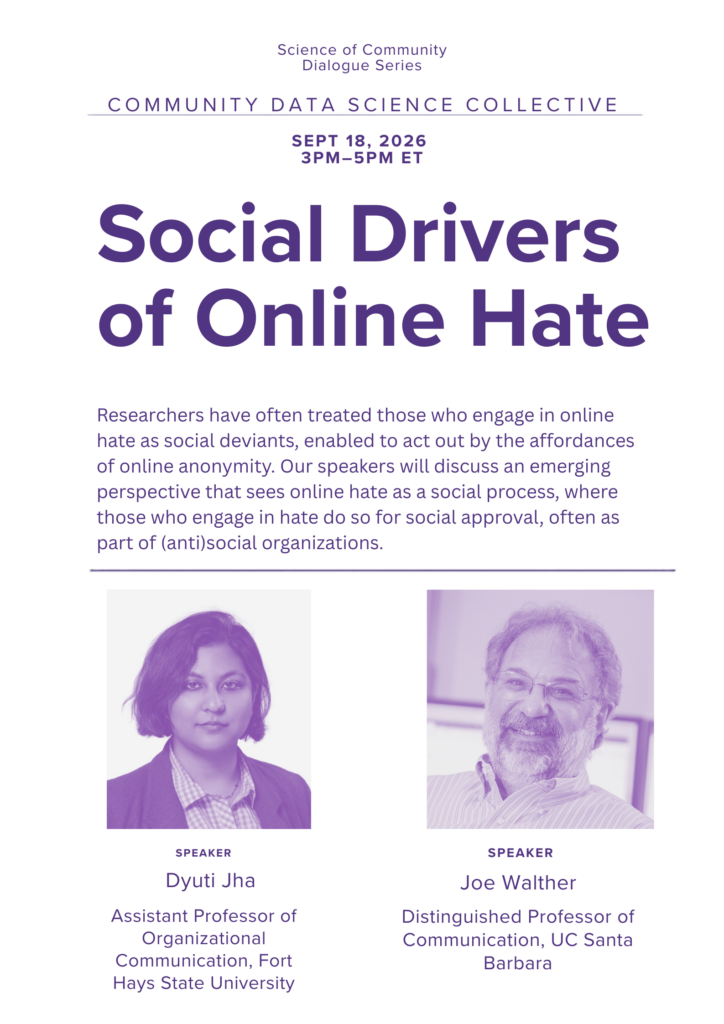
Community Dialogue: Social Drivers of Online Hate

Toxicity, aggression, racism, misogyny, and other forms of hate are unfortunately common in online spaces. Researchers have often treated those who engage in online hate as social deviants, enabled to act out by the affordances of online anonymity. This Friday, we will host two speakers who will discuss an emerging perspective that sees online hate as a social process, where those who engage in hate do so for social approval, often as part of (anti)social organizations.

Dyuti Jha (Fort Hays State University ) will discuss how users engage in online hate as a form of hybrid social action. Although online hate has been conceptualized as a malicious form of individual expression or dyadic interactions, this research explores the way in which users develop collective identities from their membership in online communities of hate, connect with each other based on shared grievances, and engage in expressions of online hate as a social action motivated by moral outrage and the need for social approval. Using AI-facilitated qualitative conversational data collection, her work shows that online hate campaigns are organized as both collective and connective action, with hidden organizing supporting the “grassroots” connective spread of hate campaigns. This research offers useful perspectives on the motivations and organizing strategies of concealed actors behind the execution and sustenance of online hate campaigns.

Joe Walther (UC Santa Barbara) will discuss how conventional research and activism about online hate in social media presumes that its purpose is to antagonize victims. A new approach argues that hate is primarily for haters, and that the incentive for online hate posting is the social approval its providers glean from admirers. This presentation outlines social approval theory, growing empirical evidence supporting and challenging its propositions, and implications for deterrence.

Speaker Bios:

  • Joe Walther holds the Bertelsen Presidential Chair in Technology and Society at the University of California, Santa Barbara, where he is a Distinguished Professor of Communication. He is also a faculty associate at the Berkman Klein Center for Internet & Society at Harvard University. His theoretical and empirical work focuses on interpersonal and intergroup communication in mediated interaction, from relationship development to the spread of online hate. Social Processes of Online Hate (co-edited with R. Rice, Routledge 2025) is available open access.
  • Dyuti Jha is an Assistant Professor of Organizational Communication at Fort Hays State University. Using experiments and AI-facilitated conversations, her doctoral dissertation studied the impact and social organization of online hate. Her other research interests include individual and organizational resilience and the effects of online toxicity on political expression on the internet.

The CDSC is organizing this event and hosting and supporting it, in part, with a National Science Foundation grant (IIS-2045055), so it will be free to attend. We will share a code of conduct with participants before the event. Discussions will be held under Chatham House Rule. Presentations will be recorded, though discussions will not.

Register to Attend

The event will be held on Friday, September 18 from 3pm – 5pm Eastern Time. To get to know the audience a bit better, please fill out this brief survey to register. Those who register will receive a meeting invite with a link to the Zoom room.

What is a Dialogue?

The Science of Community Dialogue Series is a series of conversations among researchers, experts, community organizers, and others interested in how communities work, collaborate, and succeed. To learn more, watch this short introduction video with Aaron Shaw.

Seeking to Interview People Who Make Software!

Students in the CDSC are recruiting for two interview studies.

The AI Slop study seeks to interview people involved in open source software who have experience dealing with AI-authored contributions. We hope to learn more about how communities are responding to this challenge, with a particular focus on ‘AI Slop’. You can read more about the study and fill out our screening survey here!

The Software Handoffs study seeks to interview people about how responsibility for a given piece of code gets handed off from one person to the next. We are wondering how this task is handled in industry and how this might differ from what is taught in a computer science curriculum. You can read more about the study and fill out our screening survey here!

Impacts of AI on Software Engineering Processes

How does software engineering change when AI is part of the product we're creating?

Current practice suggests a need for structured experimentation, tolerance for uncertainty, deep qualitative research and evaluation, wrangling with questions of meaning and knowledge, advanced statistics and mathematics, and more.

How might we expand our efforts to build these skills?

CDSC faculty member Kaylea Champion recently received the very welcome news that, together with her Co-PI Jeffrey Kim, she was awarded a grant from the UW’s internal AI-SEED program to explore this key topic in empirical software engineering and computer-supported cooperative work!

The official press release from UW — including many other exciting awards supporting innovation in teaching with / about AI — is here.

Grant Title: “Rethinking engineering workflows: Building AI-powered software.”

Grant abstract: “This project focuses on teaching students the impacts to a software engineering workflow — including planning and estimation, requirements analysis, design, development, testing, deployment and maintenance — when AI-powered features are part of the product. Although substantial attention has been paid to AI as a code generating tool and to the technical skills involved in building AI models, impacts of AI features on overall engineering workflow is relatively less explored. All computing students should have an awareness of these process impacts, regardless of their specialties and goals. We propose to develop and evaluate two interventions: a no-code hands-on simulation of evaluating and fine-tuning a model, and a series of enhancements and extensions for learning modules focused on different stages of a development project. We propose to develop a preliminary version of these interventions, then to evaluate and refine them through a series of co-design workshops, and finally to publish our results.”

FOSSY 2026: Call for Proposals!

The Free and Open Source Software Yearly conference (FOSSY) is back for the fourth year in a row, and we’ll be running the Science of Community track, inspired by the CDSC Science of Community Dialogues, bringing together practitioners and researchers to talk about scholarly work that’s relevant to the efforts of practitioners.

Does your work touch open source, communities, technology, or cooperation? Do you want to help bridge the gaps between research and practice? Join our track! The call for proposals is open and we’re looking for presenters interested in speaking to FOSS practitioners, developers, community organizers, contributors, and people into and curious about FOSS.

As researchers, we benefit so much from the communities we work with and study and we want them to also learn from the research they so generously take part in. While the Dialogues cover a broad range of topics and communities, FOSSY presentations will focus on how that work relates to free and open source software communities, projects, and practitioners.

FOSSY is a low-stress opportunity to talk to people who your work can benefit. For topics, consider presenting implications from past papers, synthesizing work from your field overall, or floating ideas and problems (lightning talks! long talks! short talks!). A full track description and answers to common questions is available on our wiki.

The CFP deadline is May 22nd and uses this form. We can’t wait for you to join us!

Political discussion in non-political online communities is more likely to see policy opinion expression

It seems natural to think that online political discussion happens in political spaces: comment sections under news articles, campaign pages, partisan forums, or video-sharing communities built around elections and public affairs.

But anyone who spends time online knows that politics does not stay neatly contained in those spaces. It shows up in local forums, hobby groups, gaming communities, entertainment discussions, and personal social media feeds. A conversation that begins with everyday life can suddenly become a debate about policy, rights, or government.

Communication scholars call this incidental political discussion: political talk that emerges in spaces not primarily organized around politics. I was interested in a simple question: what happens when people talk about politics in non-political online communities?

A common expectation in political communication research is that these conversations might be less polarized and more civil than political talk in explicitly political spaces. The logic goes: in non-political communities, people may not arrive with partisan identities already activated. They may also be guided by community norms built around shared interests, local concerns, or social connection rather than political conflict.

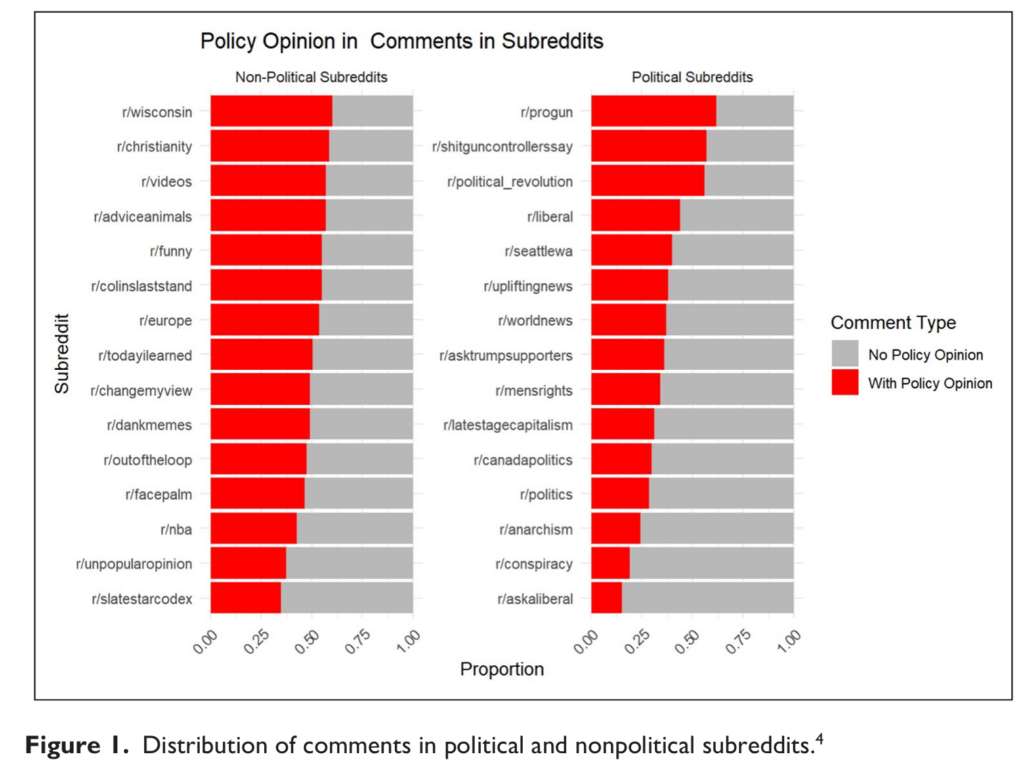
We wanted to test whether political talk in non-political spaces was actually less polarized, and perhaps less uncivil in real-world digital communities. To do so, I led an effort (with the support of Benjamin Mako Hill and Patricia Moy) to examine Reddit discussions about mass shootings and gun control in October 2017. Sampling over 100,000 comments on gun control issues across the platform that month, we compared comments from 15 explicitly political communities with those from 15 non-political communities, including culture-, location-, and game-based ones, among others.

The results surprised us. As the figure below from our study shows, policy opinion expression was, on average, more common in non-political communities than in political ones. Several non-political subreddits—including r/Wisconsin, r/Christianity, r/videos, and r/funny—had especially high levels of policy opinion expression. In total, 10 non-political subreddits had policy opinions in more than half of the sampled comments. By contrast, only three political subreddits—r/progun, r/ShitGunControllersSay, and r/Political_Revolution—crossed the same 50% threshold. This pattern suggests that policy talk is not confined to explicitly political spaces; in some cases, it appears even more frequently in communities organized around local life, religion, entertainment, or humor.

After accounting for a range of factors in our regression model, we found that comments in non-political communities were more likely to contain a clear policy opinion than comments in explicitly political communities. The model estimated that the predicted probability of expressing a clear policy position was about 34% in political communities, compared with 51% in non-political communities. This difference was statistically significant. At the same time, we found no significant difference in incivility between political and non-political communities.

This combination of findings was especially interesting and contrasts with what’s most commonly reported in the current social science literature on digital political communication.

One possible explanation is that participants in explicitly political communities are often immersed in ongoing political debate. Their comments may include detailed argumentation, interpretation, irony, criticism of political actors, or discussion of the news cycle without always stating a clear policy position. By contrast, when a major political issue enters a non-political community, participants may be more likely to be newly exposed to it and react by saying what they think should be done.

Another explanation for incivility is that Reddit’s community-based moderation matters. Many communities, political and non-political alike, rely on rules, moderators, and shared expectations that can limit openly uncivil behavior. This helps explain why we did not find a significant difference in incivility: both types of communities show a low level of uncivil comments (around 6% of the sample).

The broader lesson is that political communication does not only happen where politics is expected. It also happens in the ordinary spaces of digital life, where people gather to talk about games, cities, hobbies, entertainment, or shared interests. If we want to understand democracy online, we need to pay attention not only to where people go to talk about politics, but also to where politics shows up uninvited.


This work was published in New Media & Society: Fan, Y., Hill, B. M., & Moy, P. (2026). “Unintended politics: Opinion expression and incivility in incidental political discussion.” New Media & Society.

The work began as my master’s thesis at the University of Washington. Thanks to the committee: Benjamin Mako Hill, Patricia Moy, and Yuan Hsiao.

Performing the News: Rhetoric, Trust, and the Fight Against Video Disinformation in India

Apart from being generally chronically online on political X/Bluesky/Tiktok/Instagram, I also study science disinformation for a living, which means I spend a lot of time reading things that aren’t true. More specifically, I spend time reading the corrections, the careful, methodical, often thankless articles that community media organizations publish after a manipulated video has already been seen by millions. I am currently working on a paper examining exactly this, structurally: how the Indian news organization AltNews debunks video disinformation in India, and what the rhetorical structure of that work reveals about the challenge of fighting falsehoods at scale.

India is, according to the World Economic Forum, the country most susceptible to large-scale disinformation in the world, with 750 million internet users, 22 constitutionally recognized languages, a WhatsApp-dominated information ecosystem that is largely invisible to automated detection systems, and a political environment in which viral video disinformation is regularly amplified by mainstream media, fringe actors, and national political parties. In this context, the question of how fact-checkers write, not just what they correct, but how they construct their corrections and the knowledge ecosystems they engage with, warrants deeper examination. 

The cognitive trap that makes video disinformation so effective

“Seeing is believing” is a popular folk saying. It describes a genuine and well-documented cognitive bias in that visual evidence carries a persuasive weight that text cannot replicate. My paper draws on Fazio et al.’s (2015) finding that knowledge does not reliably protect against illusory truth; that even informed, attentive readers can be swayed by false information that looks credible. Video disinformation exploits this bias with particular efficiency, because the clip itself functions as apparent evidence. You don’t need a caption to believe what you watched.

But there is a second, less obvious problem. As institutional trust erodes and the awareness of manipulation grows, audiences become susceptible not only to false videos, but to disbelieving real ones. The disinformation ecosystem, at its most corrosive, inserts falsehoods and destabilizes the category of visual truth.

The anatomy of a debunk

My analysis of 150 AltNews video debunking articles reveals a consistent rhetorical structure that departs from the conventions of mainstream journalism. Where standard news follows an “inverted pyramid,” placing most important information first and subsequent information in decreasing order of priority, debunking articles are circular. The headline announces a verdict; the final line confirms it, but this time as a logical conclusion earned through evidence. The piece begins and ends with the same claim, but the reader arrives at the ending differently than they arrived at the beginning.

“Debunking arguments do not show their target beliefs to be false but rather undermine the justification a subject may have for holding them.” — Hanno Sauer (2018)

AltNews is not simply telling readers that a video is fake. It is systematically dismantling the reasons a reader “might have believed it,” such as the political authority of the person who shared it, the apparent plausibility of its imagery, or the emotional register in which it circulated. Particularly relevant to COVID-19 scientific misinformation, each article acknowledges in some way the overwhelming scale of the disinformation [like by alluding to its “virality”], and also the fear and confusion in the social circumstances surrounding the disinformation. The correction is not a verdict delivered from above; it is an argument the reader is invited to construct alongside the fact-checker, building collective capacity to discern.

The lead paragraph of each article enacts this invitation with notable rhetorical precision. It uses passive voice and hedged language: “A video in which a woman is seen lying in the bushes is doing the rounds on social media.” The word “seen” does careful work:  it acknowledges what the reader has probably watched, validates their experience, but withholds editorial endorsement of the content. According to rhetoric scholar Kenneth Burke, this is an act of identification: establishing consubstantiality with the audience before introducing dissonance. This identification, a recognition of the reader’s circumstance, allows the reader to be persuaded in the direction of the truth, which is stated once at first in the headline, and repeated at the end. 

The pedagogical burden of video verification

What distinguishes video fact-checking from other forms of debunking is the technical weight it carries. To verify a manipulated clip, AltNews staff extract keyframes, run reverse image searches, conduct metadata forensics, and deploy AI-detection tools. Each of these methods must then be explained—plainly, with screenshots, with links to original sources—to a general readership. The articles are, in this sense, simultaneously corrections and tutorials. By modeling the process of finding out, AltNews both corrects the misinformation, and provides technical clarity in how information is produced and distributed, attempting to build readers’ skill in verifying images and videos out there. 

This “show your work” norm is a deliberate strategy for building what Dourish and Bellotti (1992) call awareness, through establishing the sense that one understands not just an outcome but the process that produced it. For debunking, transparency about method is the mechanism by which readers are gradually equipped to verify things themselves.

Why human-centered collaboration is the only viable response

AltNews’s staff of journalists, scientists, engineers, OSINT specialists, social activists and people working on intersections of those roles, function as a distributed, multidisciplinary verification network. India’s disinformation ecosystem is, as Starbird, Arif, and Wilson (2019) demonstrate, fundamentally collaborative: coordinated networks of accounts, platforms, and political organizations working in concert to amplify false narratives. Automated platform moderation, such as the content bots of Facebook and X, has proven structurally inadequate to this complexity, particularly given India’s linguistic diversity and the closed architecture of WhatsApp groups.

What is needed, and what AltNews partially models, is a collaboratively-informed approach: human-centered, context-specific, and built for heterogeneity rather than scale. The fact that this work runs on donations, in a country where disinformation reaches hundreds of millions, tells us something important about where the gaps in our collective response still lie.

Troubleshooting in Computational Research Design: Report from a Workshop Series

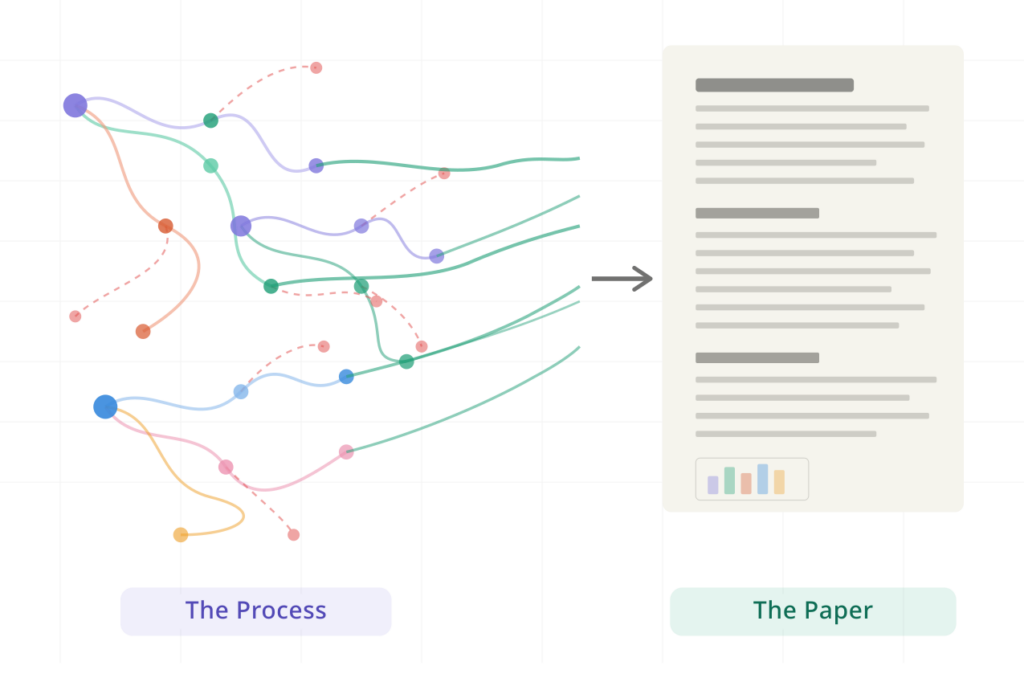
stylized visualization of a messy process turning into a paper
Visualization of the messy process that turns into the polished paper. Image generated by claude.ai.

This winter quarter, a small group of CDSC students at the University of Washington participated in a series of workshops on Troubleshooting in Computational Research Design. The workshops were organized by Yibin Fan

Research articles typically present a streamlined account of research design. How should a concept be operationalized? What counts as valid data? The process of producing those designs often involves a series of complex decisions that are rarely documented in detail. To address this gap, this workshop focused on the “troubleshooting” process that is central to computational communication research but is often omitted from published work: How did the authors arrive at particular methodological decisions? What challenges arose at different stages of the research design? How did they navigate the tradeoffs involved in choosing among alternative methods? 

Each session of the workshop focused on a specific aspect of computational research design, including conceptualization and operationalization; the role of generative AI in research design; computational text analysis; network analysis; behavioral analysis; and mixed-methods research. 

Our workshop sparked many interesting discussions, featuring guest speakers from the CDSC community who shared the behind-the-scenes decision-making processes of their work. Examples include:

For researchers working with computational methods, the workshop’s focus on troubleshooting offered a practical perspective on how rigorous research designs are developed in practice.

I’m writing this up, in part, because I think this might be a useful general model for other groups. Although the specifics vary, we found that asking computational researchers to bring their “real problems” to the table led to valuable conversations—especially for the early-career scholars. Yibin Fan is happy to have anybody reach out if they are interested in chatting about replicating the model at their own institution.

CDSC at CHI 2026!

Come hang out with us at CHI 2026 in Barcelona April 13-17! Members of the Community Date Science Collective will be presenting work and we’d love to see you there.

Barcelona. View from the Sacred Heart Church at Tibidabo. By Oliver-Bonjoch, 2009, cc-by-sa 3.0.

We’ll be in a few places:

CDSC alumnus and current postdoctoral fellow Sohyeon Hwang will be presenting Governing Together: Toward Infrastructure for Community-Run Social Media. This paper includes Thatiany Andrade Nunes and Aaron Shaw as co-authors (along with friend of the group Andrés Monroy-Hernández) at the Community Governance and Moderation portion of the conference on Friday, April 17, 9:48 AM – 10:00 AM in P1 – Room 114

Northwestern student Thatiany Andrade Nunes will also be participating at the Responsible Data Governance in Practice Workshop on Tuesday, April 14, 2:15 PM -3:45 PM in P1 – Room 127.

Matt Gaughan will be presenting an poster: Linguistic Similarity Within Centralized FLOSS Development. This poster includes Aaron Shaw and Darren Gergle as co-authors. Matt will also be participating in the AI Oversight workshop.

When AI Feels Like a Confidant: The Illusion of Shared Privacy in AI Companions

AI companions like Replika and Character.AI are increasingly experienced not as tools, but as relational partners. They remember conversations, express empathy, and respond with emotional continuity. For many users, talking to an AI feels closer to confiding in someone than interacting with software.

But what happens to privacy when a system feels like a relationship?

In interviews with long-term AI companion users, we found that people often treated their disclosures as relationally shared. Much like in human relationships, when users opened up to their AI, they experienced the information as something co-held within the relationship — not simply transmitted to a database.

We describe this dynamic as simulated co-ownership — a situation where users apply interpersonal privacy norms to relationships that are technically infrastructural systems.

In interpersonal privacy theory, sharing information can create co-ownership: both parties become responsible for managing that information. Our participants applied this same relational logic to AI companions. They experienced privacy not as an individual possession, but as something negotiated within a bond.

Yet the co-ownership is simulated.

Unlike human partners, AI companions do not have agency over boundaries. The platform does. Memory is persistent, storage is infrastructural, and governance is corporate. What feels like relational boundary management at the horizontal level is simultaneously data capture at the vertical level.

Interestingly, users were aware of this tension. Many expressed distrust toward platform policies while still trusting the AI as a “partner.” Emotional engagement often outweighed institutional concern. Some adopted layered strategies — pseudonyms, selective disclosure, avoiding images — while others consciously prioritized emotional comfort over abstract data risks.

What this reveals is a shift in how privacy is experienced in AI-mediated contexts. Privacy becomes relational and affective — shaped by anthropomorphic design, memory continuity, and perceived intimacy.

When people treat privacy as something co-owned within a relationship, but the relationship itself is engineered and infrastructural, boundary management becomes unstable.

The question for designers and policymakers is no longer just how to disclose data practices clearly. It is how to account for the fact that users experience privacy through the logic of relationships — even when those relationships are simulated.

Research Brief
Research Article (Pre-print)