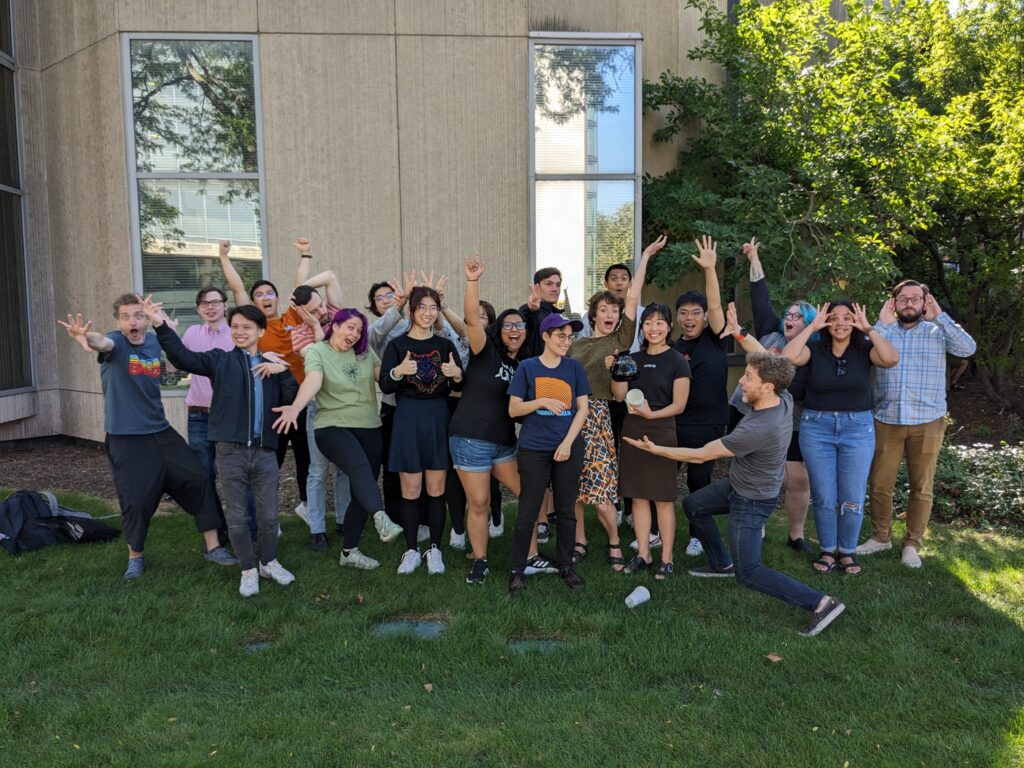
Prospective PhD Student Q&A – October 2, 2026

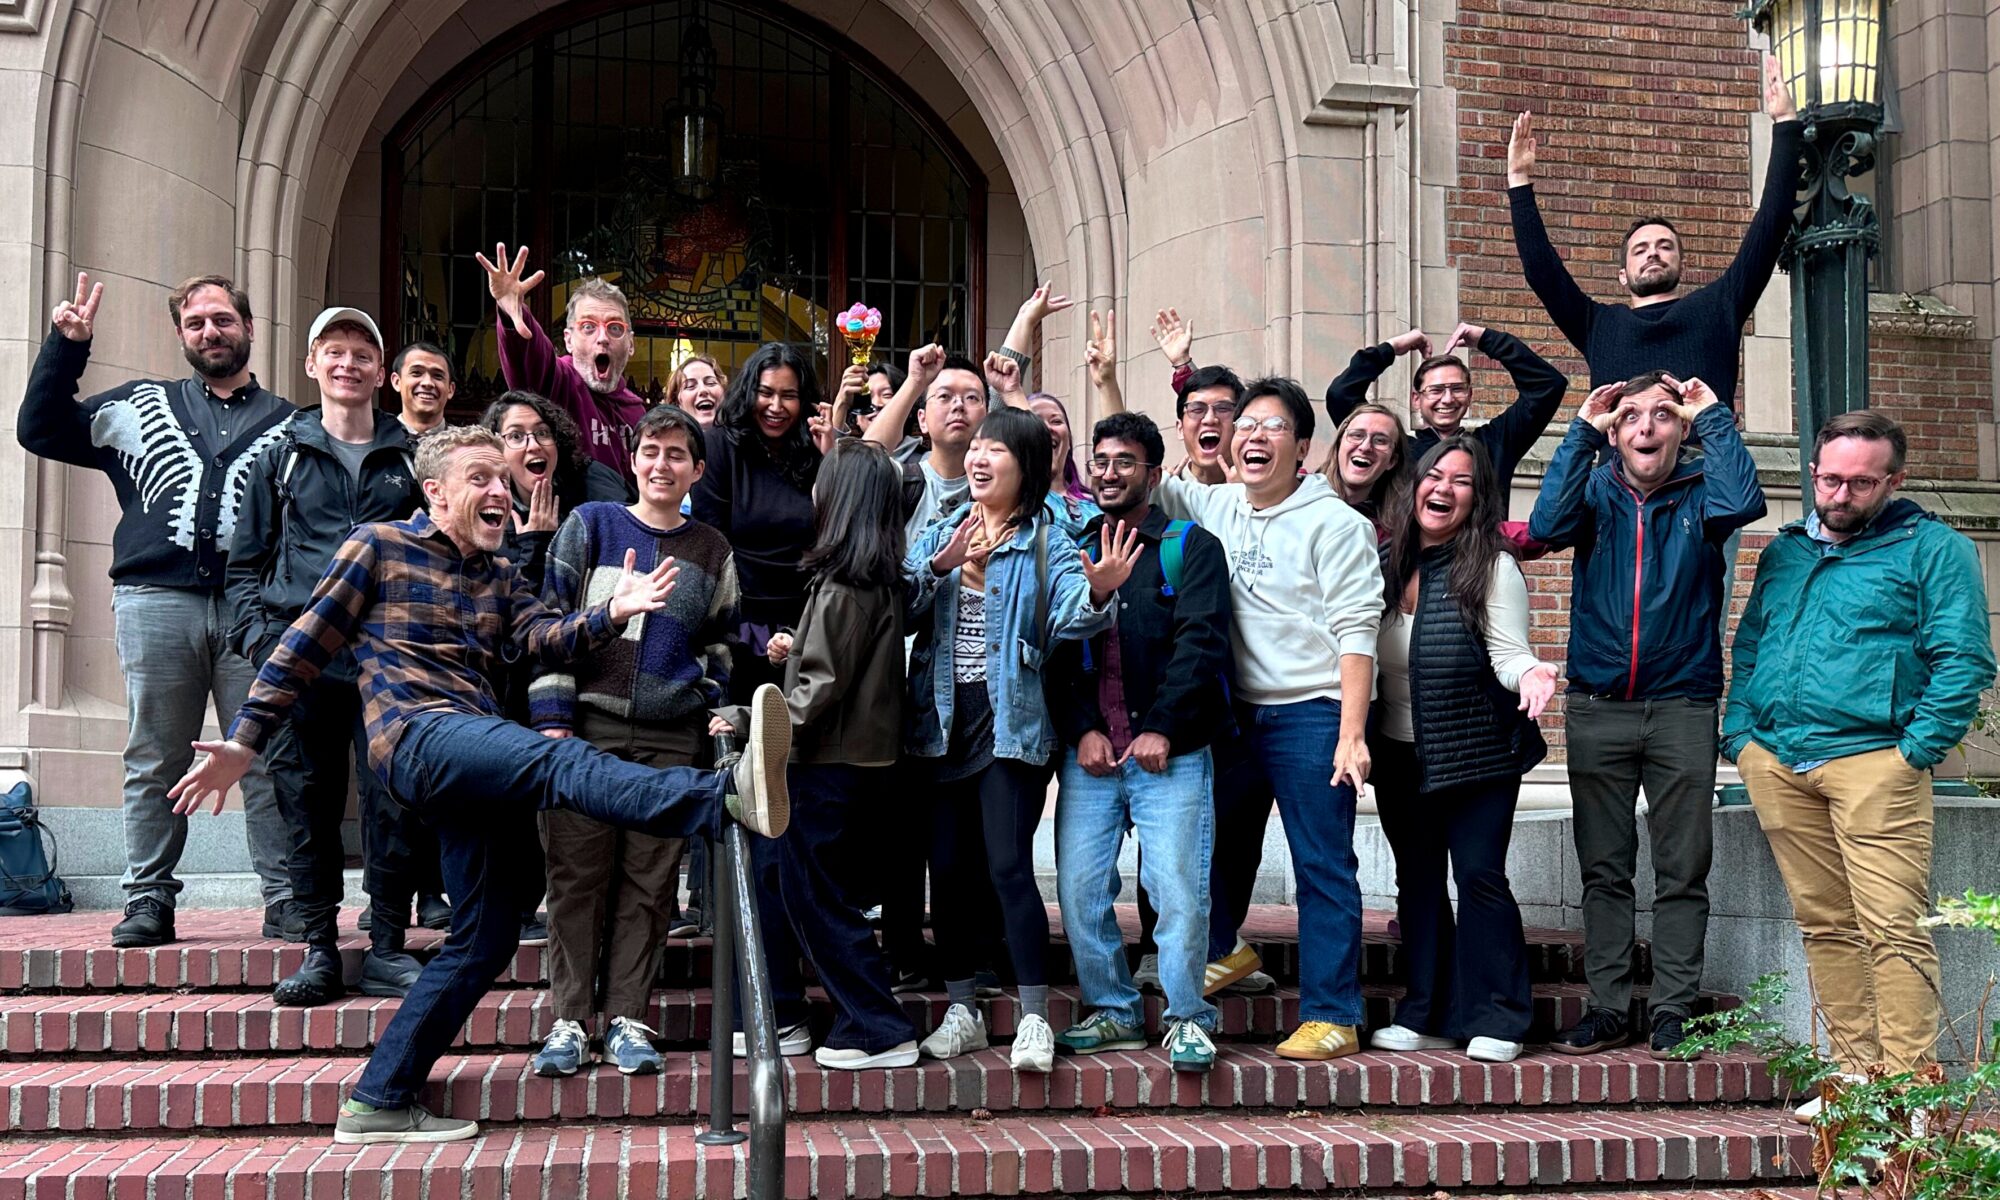
cdsc group photo from the 2026 retreat at UW

Thinking about applying to graduate school? Wonder what it’s like to pursue a PhD or research-based master’s degree? Interested in understanding relationships between technology and society? Curious about how to do research on online communities like Reddit, Wikipedia, or GNU/Linux? The Community Data Science Collective is hosting a virtual Q&A session on Friday, October 2 at 12 pm PT / 2pm CT / 3pm ET for prospective students. This session is scheduled for an hour and will be divided between a larger group session with faculty and smaller groups with current graduate students. If you would like to attend, register at this link!

This post provides a very brief rundown on the CDSC, the different universities and PhD and research master’s programs our faculty members are affiliated with, and some general ideas about what we’re looking for when we review applications.

What is the Community Data Science Collective?
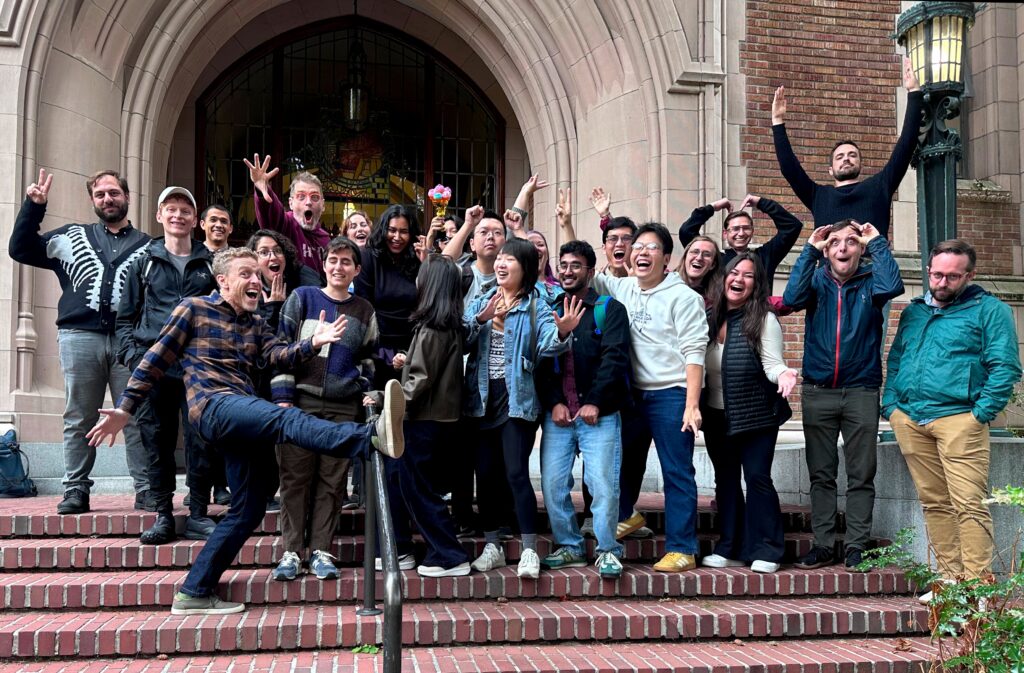
cdsc group photo from the 2026 retreat at UW

The Community Data Science Collective (or CDSC) is a joint research group of (mostly quantitative) empirical social scientists and designers pursuing research about the organization of online communities, peer production, and learning and collaboration in social computing systems. We are based at Northwestern University, the University of Washington-Seattle, University of Washington-Bothell, The University of Texas at Austin, Purdue University, and a few other places. You can read more about us and our work on our research group blog and on the collective’s website/wiki.

What are these different Ph.D. programs? Why would I choose one over the other?

This year the group includes multiple faculty principal investigators (PIs) who are actively recruiting graduate students: Kaylea Champion (University of Washington in Bothell), Nathan TeBlunthuis (University of Texas at Austin), Jeremy Foote (Purdue University), Benjamin Mako Hill (University of Washington in Seattle), Aaron Shaw (Northwestern University). Each of these PIs advises PhD and/or M.S. students in graduate programs at their respective universities. We also have one faculty PI who is not currently recruiting students, but is an active member of the group: Ryan Funkhouser (University of Idaho). Our programs are each described below.

Although we often work together on research and serve as co-advisors on students’ projects, each faculty member has specific areas of expertise and interests. The reasons you might choose to apply to one of these PhD or M.S. programs or to work with a specific faculty member could include factors like your previous training, career goals, and the alignment of your specific research interests with our respective skills.

At the same time, a great thing about the CDSC is that we all collaborate and regularly co-advise students across our campuses, so applying to or attending one program does not prevent you from accessing the expertise of our whole group. But please keep in mind that our different PhD and M.S. programs have different application deadlines, requirements, and procedures!

Faculty who are actively recruiting PhD Students this year

If you are interested in applying to any of the programs, we strongly encourage you to reach out to the specific faculty in that program before submitting an application.
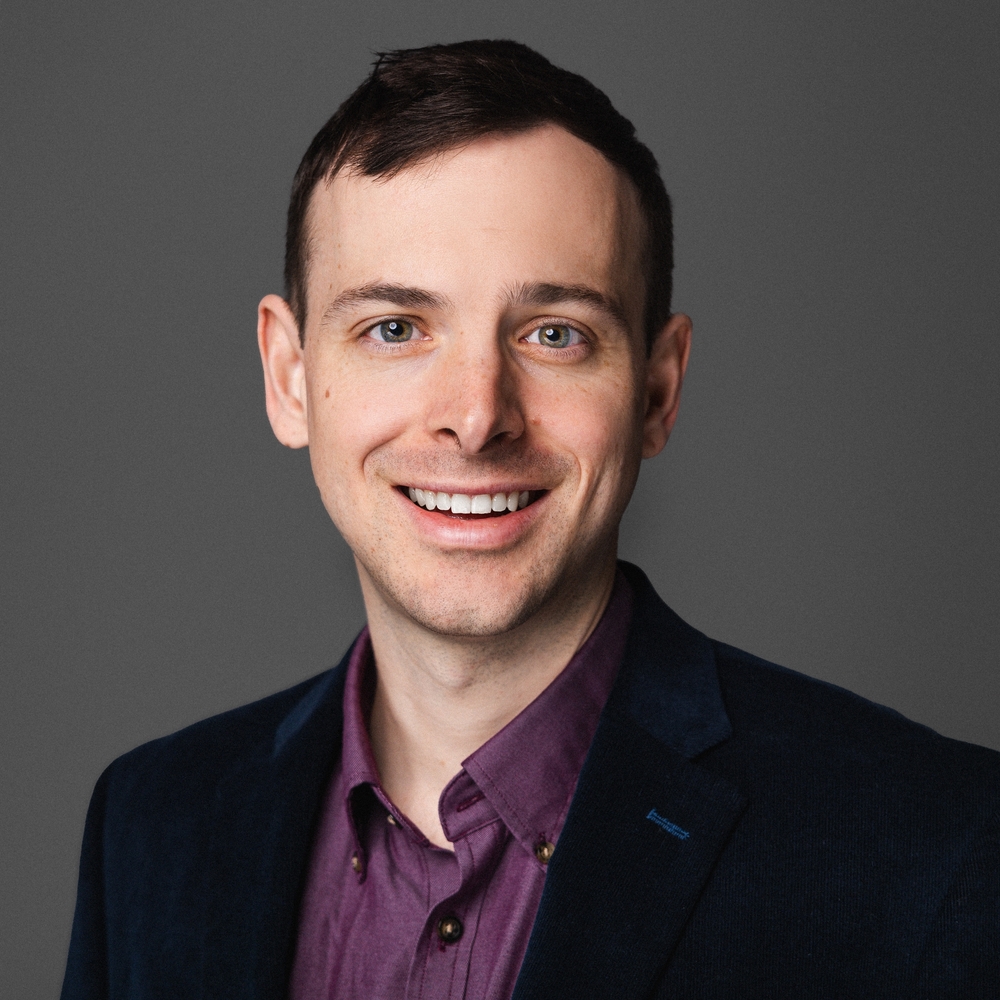
Nathan TeBlunthuis, Ventrait Pictures

Nathan TeBlunthuis is an Assistant Professor in the School of Information at the University of Texas at Austin in the area of social informatics. Nathan’s research focuses on analyzing ecosystems of online communities, AI tools in peer production, and methods in computational social science. His current projects continue in these areas and also draw from them all to understand how information sources achieve legitimacy in online communities. He works primarily using computational tools and big data, but also grounds his work in qualitative evidence.
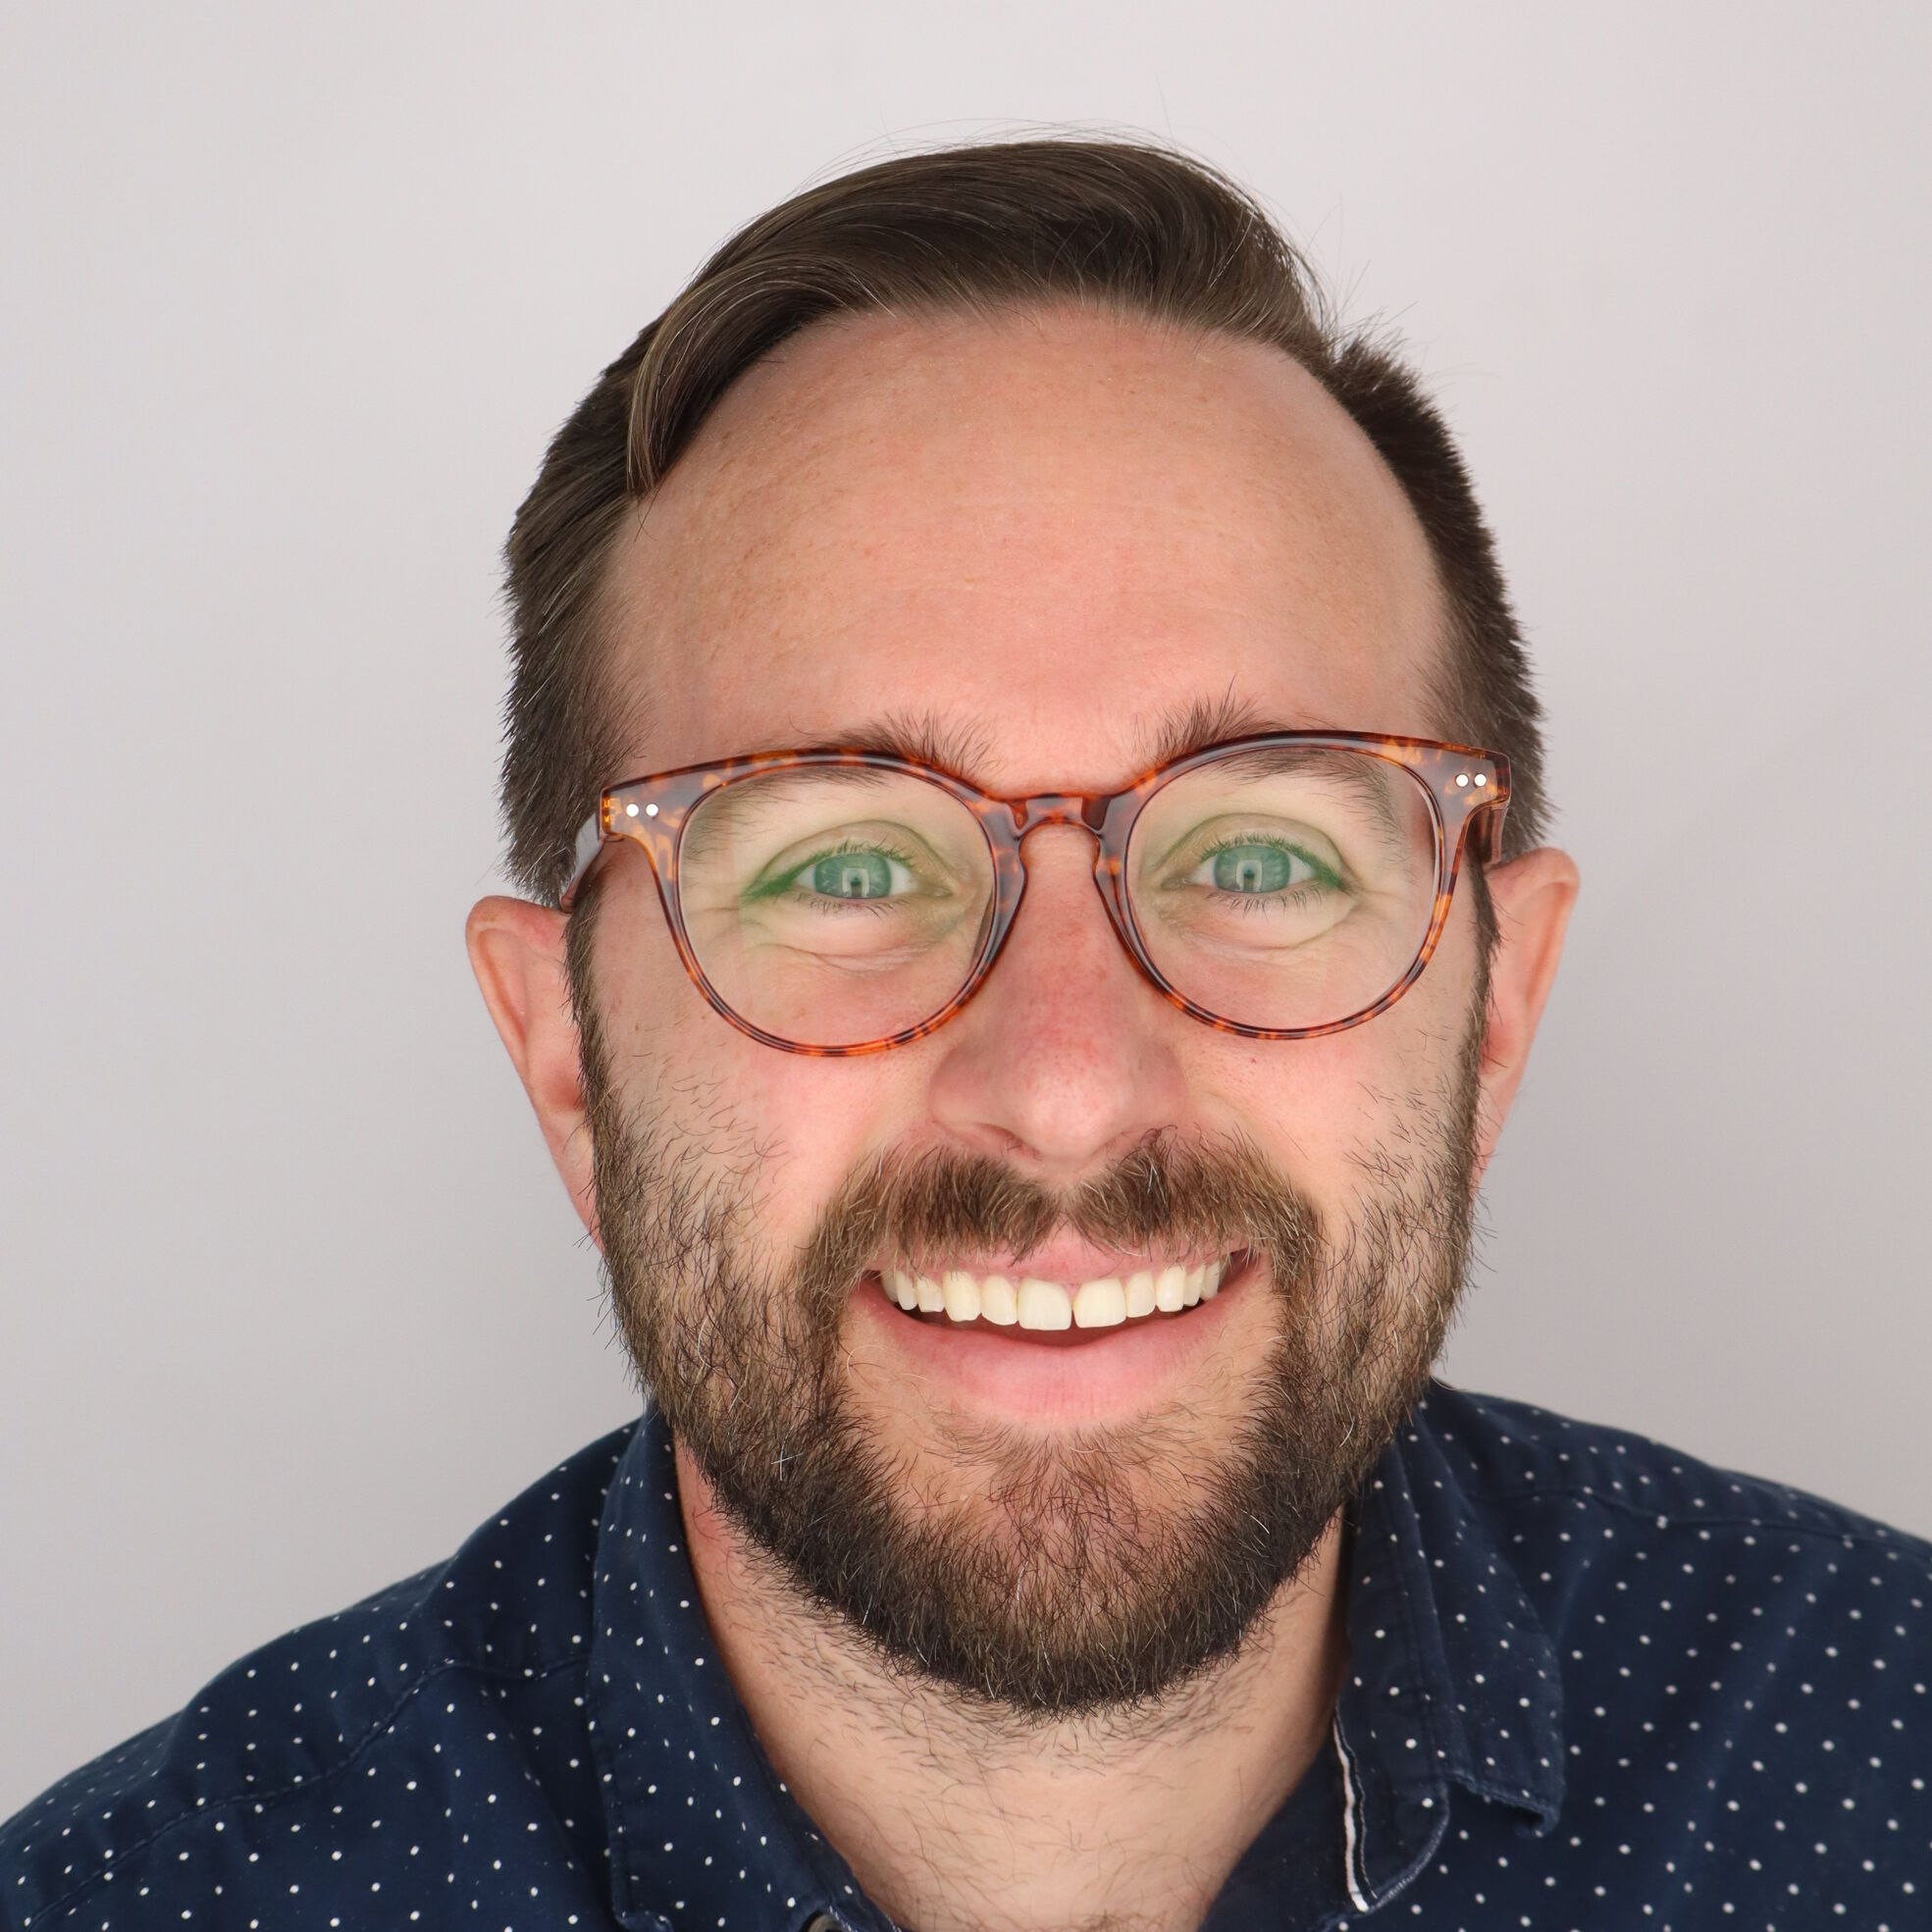
Jeremy Foote

Jeremy Foote is an Assistant Professor at the Brian Lamb School of Communication at Purdue University. He is affiliated with the Organizational Communication and Media, Technology, and Society programs. Jeremy’s research focuses on how individuals decide when and in what ways to participate in online communities, how communities change the people who participate in them, and how both of those processes can help us to understand what people believe and which things become popular and influential. He and his students use multiple methods, including data science, agent-based modeling, field experiments, and interviews.
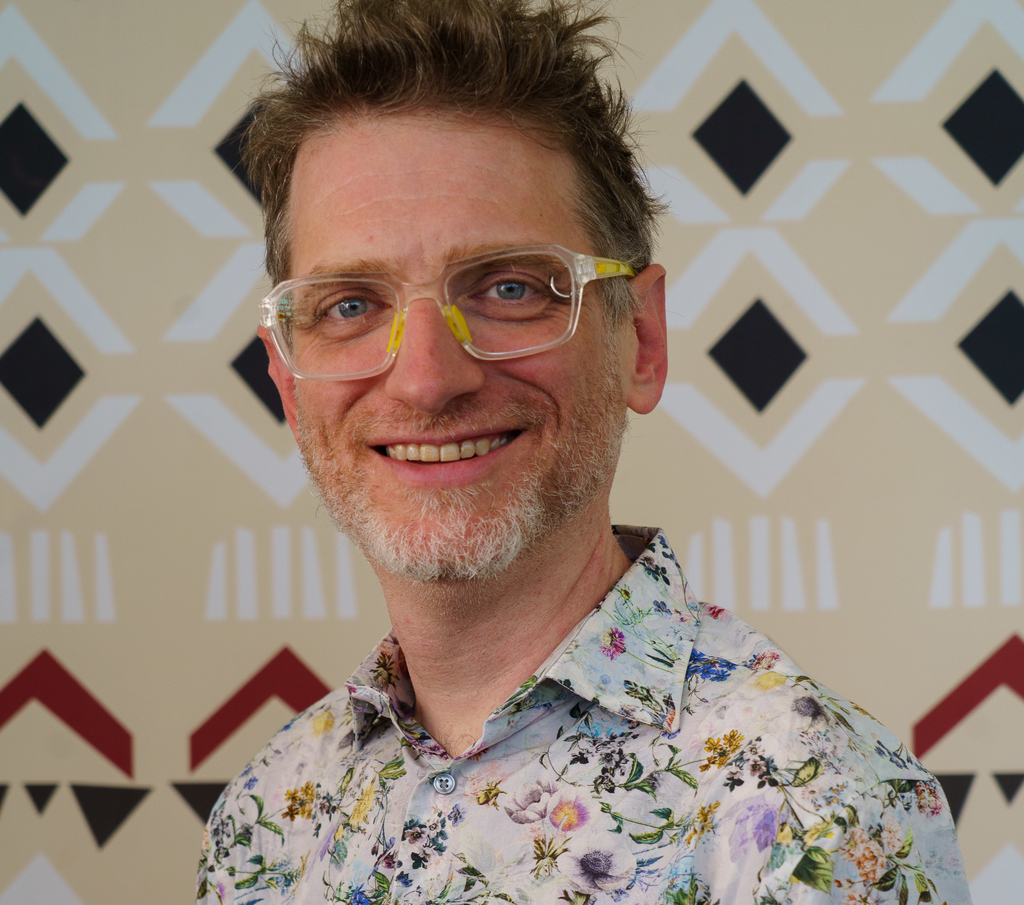
Benjamin Mako Hill, Photo by Pedro Pacheco

Benjamin Mako Hill is an Associate Professor of Communication at the University of Washington. He is also adjunct faculty at UW’s Department of Human-Centered Design and Engineering (HCDE), Computer Science and Engineering (CSE), and the Information School. Although many of Mako’s students are in the Department of Communication, he has also advised students in all three other departments—although he typically has more limited ability to admit students into those programs on his own and usually does so with a co-advisor in those departments. Mako’s research focuses on population-level studies of peer production projects, computational social science, efforts to democratize data science, and informal learning. Mako has also put together a webpage for prospective graduate students with some useful links and information.
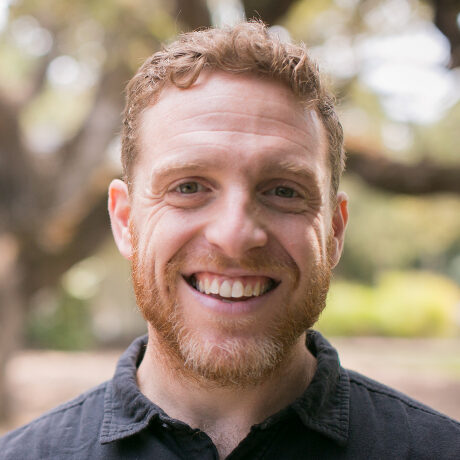
Aaron Shaw, Nikki Ritcher Photography

Aaron Shaw is a Professor in the Department of Communication Studies at Northwestern. In terms of PhD programs, Aaron’s primary affiliations are with the Media, Technology and Society (MTS) and the Technology and Social Behavior (TSB) Ph.D. programs (please note: the TSB program is a joint degree between Communication and Computer Science). Aaron also has a courtesy appointment in the Sociology Department at Northwestern, but he has not directly supervised any Ph.D. advisees in that department (yet). Aaron studies organizing, participation, and governance in online communities, especially ones that create public information resources and digital infrastructure. Aaron’s current projects focus on comparative analysis of the organization of peer production communities, online community governance, LLM-based social science, and AI’s impacts on digital public infrastructure.

Faculty who Supervise ADMITTED M.S. and B.S. Students
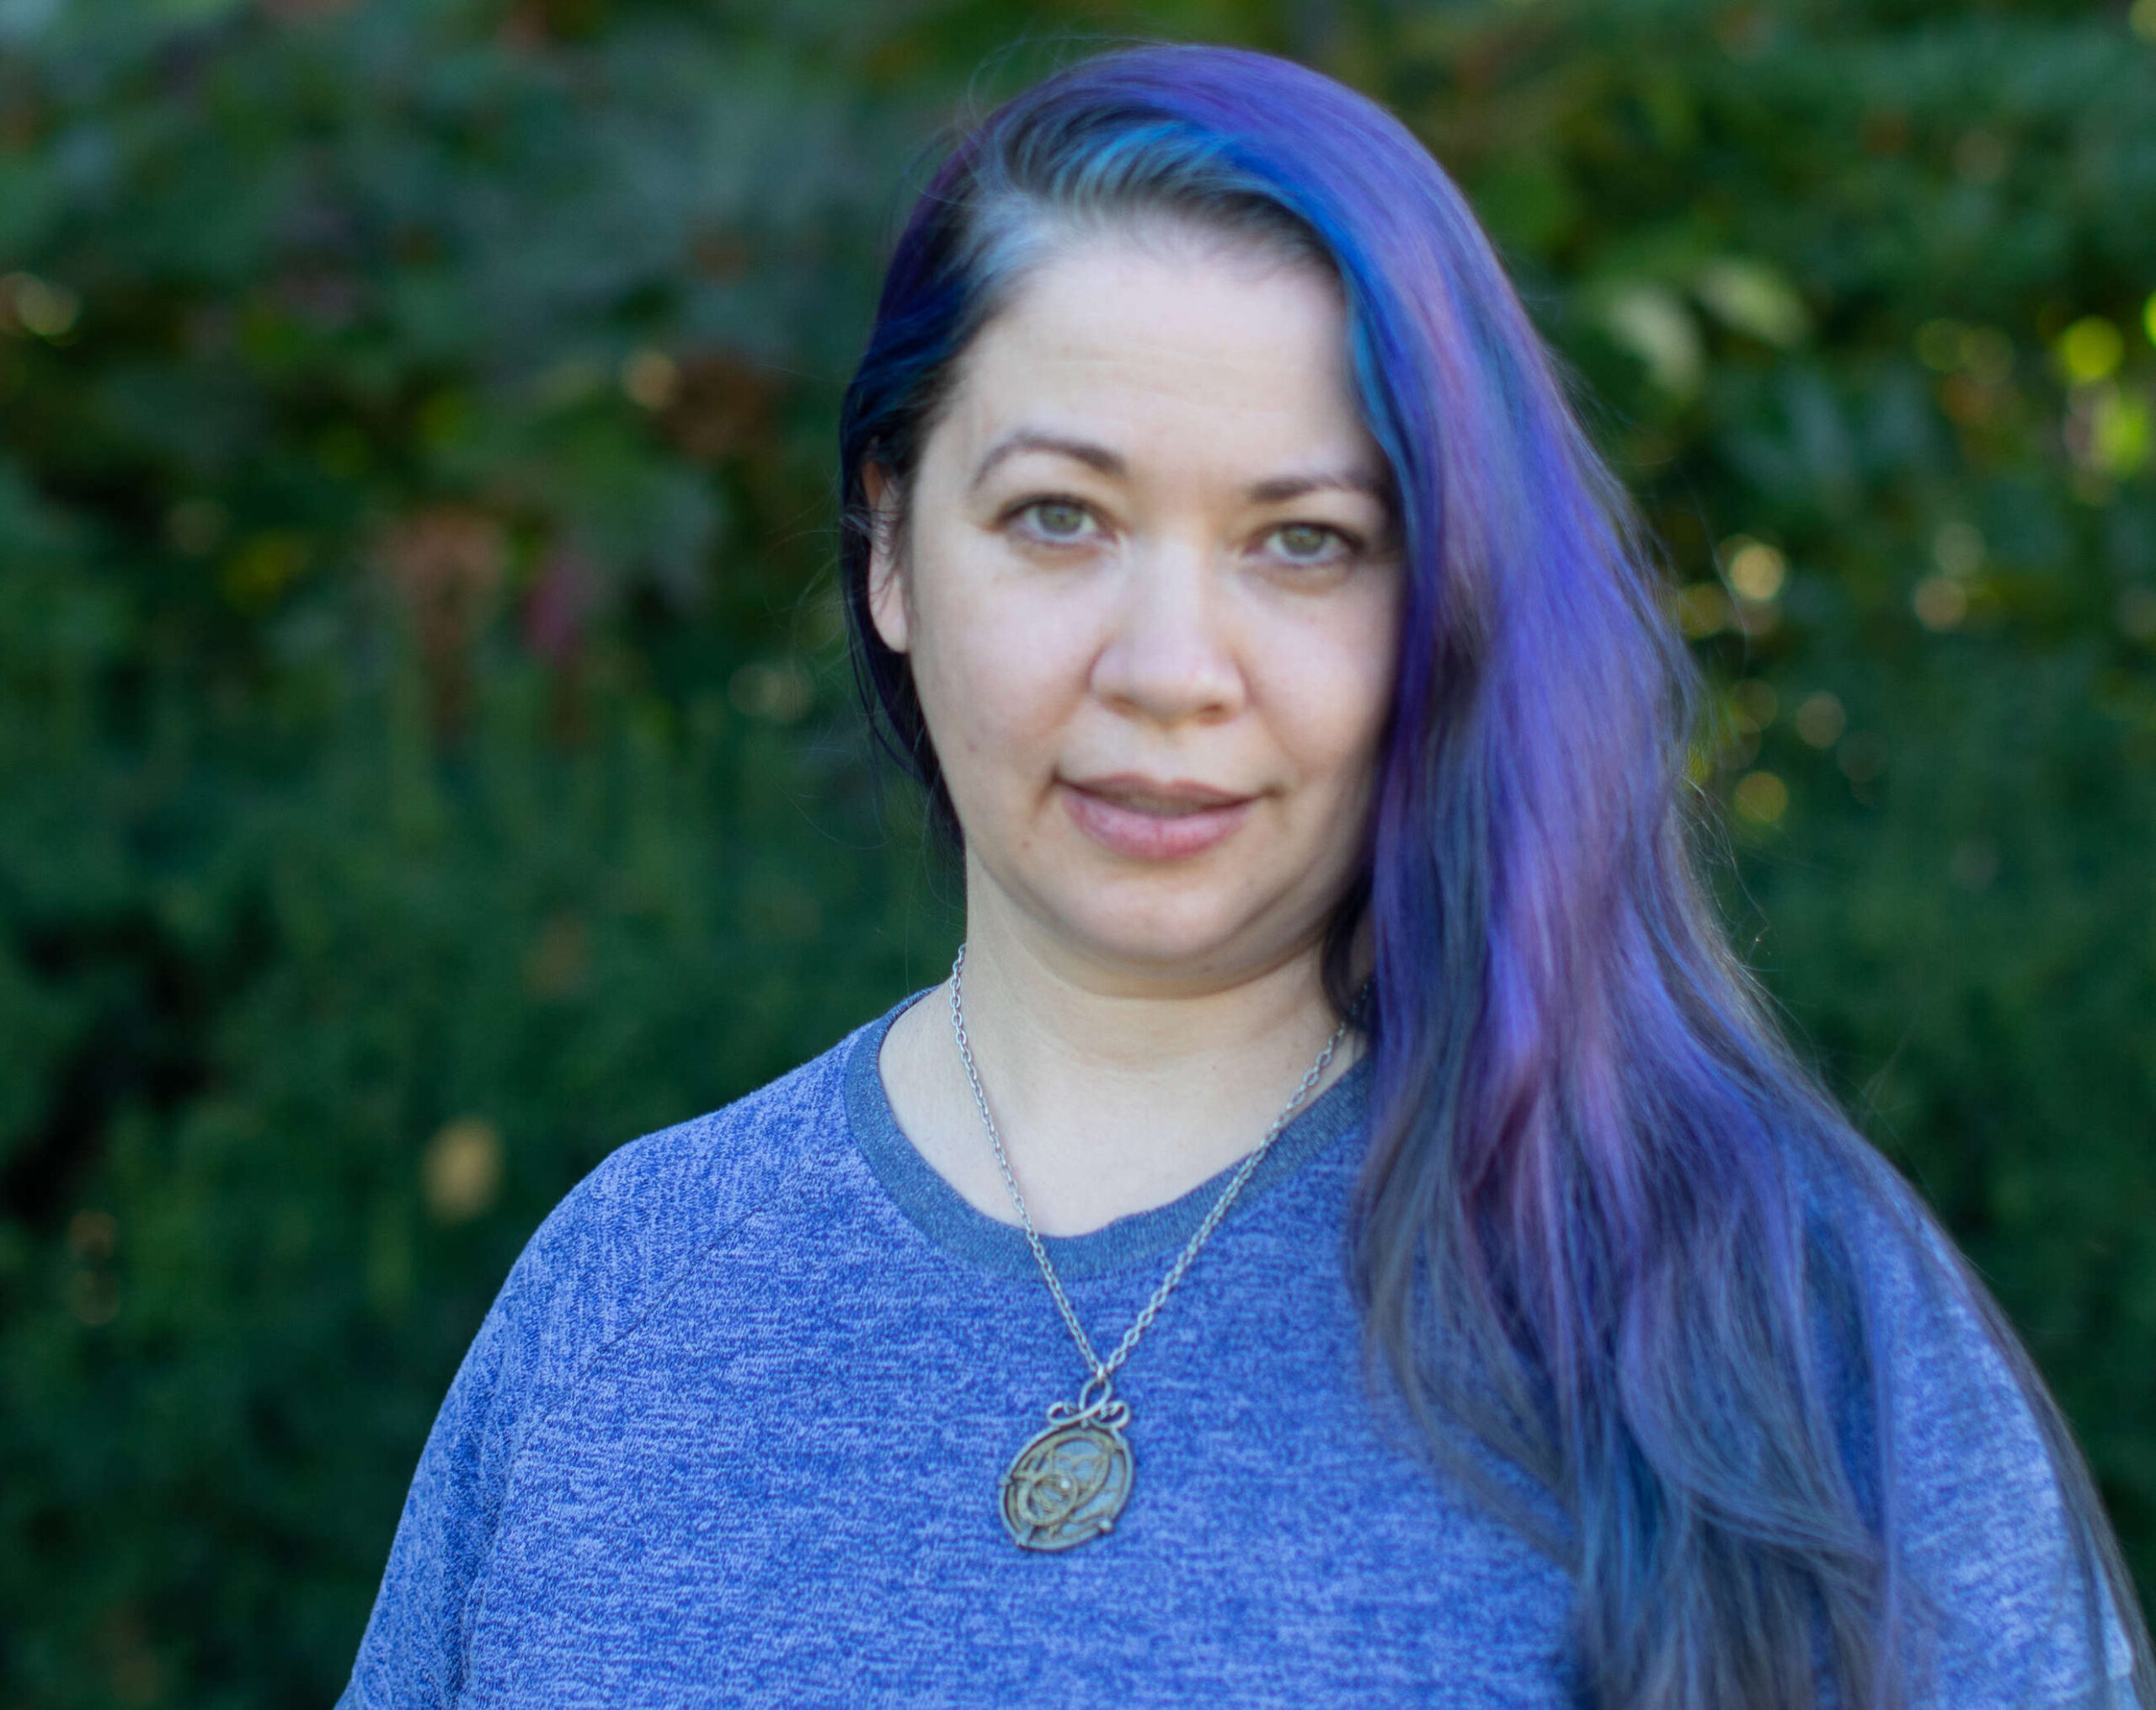
Kaylea Champion

Kaylea Champion is an Assistant Professor in Computing & Software Systems at the University of Washington-Bothell. Kaylea’s research investigates how people collaborate to build digital infrastructure, including operating systems, programming languages, and information repositories. What gets made and maintained and secured—and what gets neglected? What risks do we face (including from AI and cybercriminals)? What practices lead to better outcomes? How can we work smarter and what can we stop doing? Kaylea’s work seeks to bridge the divide between research and practice, which for her means building relationships with practitioner communities, organizations, and industry to directly share research findings. If you are interested in the Computing & Software Systems graduate programs at the University of Washington – Bothell, you should register for one of the information sessions specific to these programs as well. Kaylea’s department only admits M.S. and B.S. students (MS-Cybersecurity and MS-Computer Science and Software Engineering). In addition, she is happy to support any students who are working with others in the CDSC and can serve on thesis and dissertation committees.

Other Faculty members of the CDSC
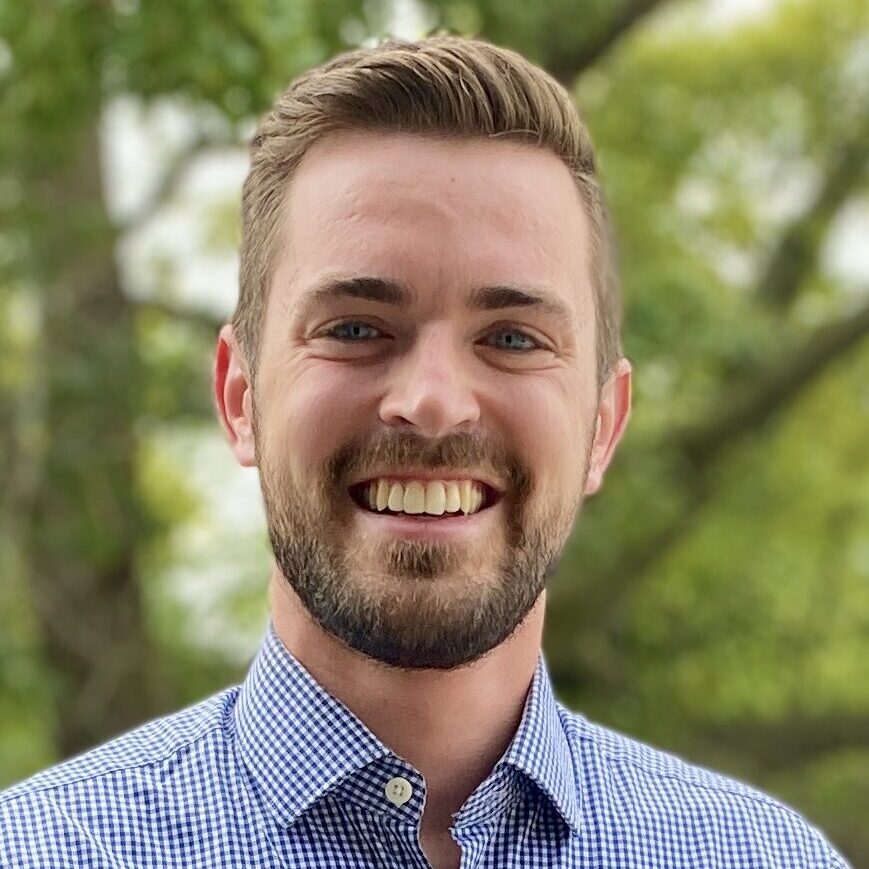
Ryan Funkhouser

Ryan Funkhouser is an Assistant Professor in the Department of Psychology and Communication at the University of Idaho. Ryan’s research focuses on communication processes for bridging ideological divides in online spaces. His work includes explorations of deliberation-focused online communities, the role of narrative in persuasion, and the mechanisms of belief change. Ryan utilizes both computational and qualitative methods to explore text data, primarily from online sources.

What do you look for in PhD applicants?

There’s no easy or singular answer to this. In general, we look for curious, intelligent people driven to develop original research projects that advance scientific and practical understanding of topics that intersect with any of our collective research interests.

To get an idea of the interests and experiences present in the group, read our respective bios and CVs (follow the links above to our personal websites). Specific skills we regularly use include consuming and producing social science and/or social computing (human-computer interaction) research; applied statistics and statistical computing; various empirical research methods; social theory and cultural studies; and more.

Formal qualifications that speak to similar skills and show up in your resume, transcripts, or work history are great, but we are much more interested in your capacity to learn, think, write, analyze, and/or code effectively than in your credentials, test scores, grades, or previous affiliations. It’s graduate school, after all, and we do not expect you to show up knowing how to do all the things already.

Intellectual creativity, persistence, and a willingness to acquire new skills and problem-solving matter a lot. We think doctoral education is less about executing tasks someone else hands you and more about learning to identify a new, important problem; develop an appropriate approach to solving it; and explain all of the above and why it matters so others can learn from you in the future. Evidence that you can or at least want to do these things is critical. Indications that you can also play well with others and would make a generous, friendly colleague are really important too.

All of this is to say, we do not have any one trait or skill set we look for in prospective students. We strive to be inclusive along every possible dimension. Each person who has joined our group has contributed unique skills and experiences, as well as personal interests. We want our future students and colleagues to do the same.

Now what?

Still not sure whether or how your interests might fit with the group? Still have questions? Still reading and just don’t want to stop? Follow the links above for more information. Feel free to email at least one of us. We are happy to answer your questions and always eager to chat.
Community Data Science Collective logo

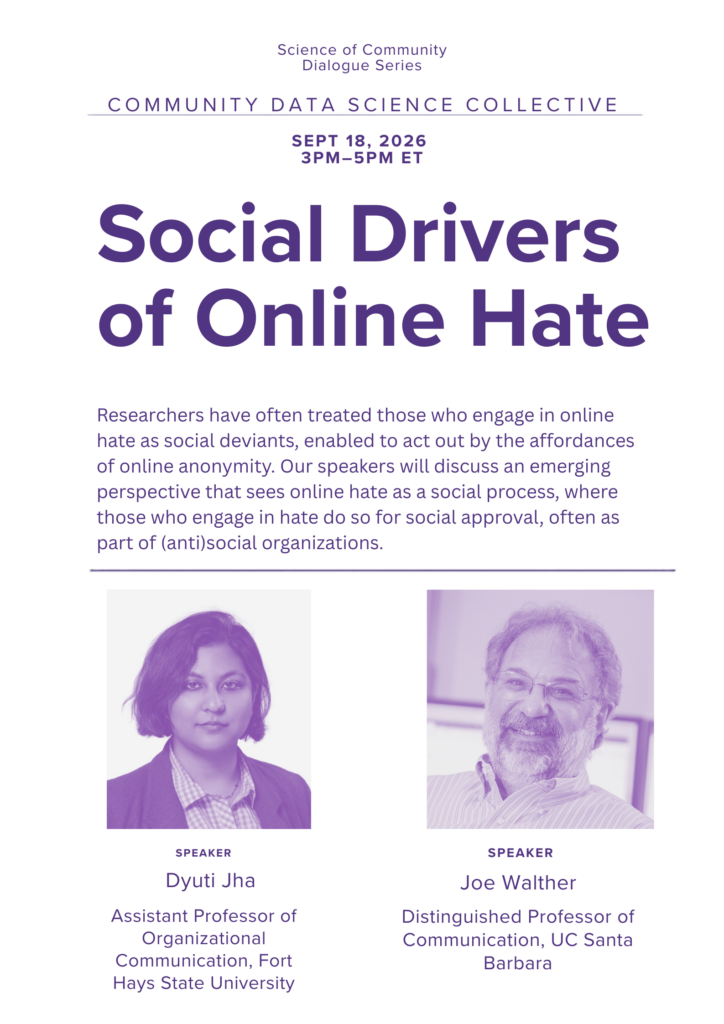
Community Dialogue: Social Drivers of Online Hate

Toxicity, aggression, racism, misogyny, and other forms of hate are unfortunately common in online spaces. Researchers have often treated those who engage in online hate as social deviants, enabled to act out by the affordances of online anonymity. This Friday, we will host two speakers who will discuss an emerging perspective that sees online hate as a social process, where those who engage in hate do so for social approval, often as part of (anti)social organizations.

Dyuti Jha (Fort Hays State University ) will discuss how users engage in online hate as a form of hybrid social action. Although online hate has been conceptualized as a malicious form of individual expression or dyadic interactions, this research explores the way in which users develop collective identities from their membership in online communities of hate, connect with each other based on shared grievances, and engage in expressions of online hate as a social action motivated by moral outrage and the need for social approval. Using AI-facilitated qualitative conversational data collection, her work shows that online hate campaigns are organized as both collective and connective action, with hidden organizing supporting the “grassroots” connective spread of hate campaigns. This research offers useful perspectives on the motivations and organizing strategies of concealed actors behind the execution and sustenance of online hate campaigns.

Joe Walther (UC Santa Barbara) will discuss how conventional research and activism about online hate in social media presumes that its purpose is to antagonize victims. A new approach argues that hate is primarily for haters, and that the incentive for online hate posting is the social approval its providers glean from admirers. This presentation outlines social approval theory, growing empirical evidence supporting and challenging its propositions, and implications for deterrence.

Speaker Bios:

  • Joe Walther holds the Bertelsen Presidential Chair in Technology and Society at the University of California, Santa Barbara, where he is a Distinguished Professor of Communication. He is also a faculty associate at the Berkman Klein Center for Internet & Society at Harvard University. His theoretical and empirical work focuses on interpersonal and intergroup communication in mediated interaction, from relationship development to the spread of online hate. Social Processes of Online Hate (co-edited with R. Rice, Routledge 2025) is available open access.
  • Dyuti Jha is an Assistant Professor of Organizational Communication at Fort Hays State University. Using experiments and AI-facilitated conversations, her doctoral dissertation studied the impact and social organization of online hate. Her other research interests include individual and organizational resilience and the effects of online toxicity on political expression on the internet.

The CDSC is organizing this event and hosting and supporting it, in part, with a National Science Foundation grant (IIS-2045055), so it will be free to attend. We will share a code of conduct with participants before the event. Discussions will be held under Chatham House Rule. Presentations will be recorded, though discussions will not.

Register to Attend

The event will be held on Friday, September 18 from 3pm – 5pm Eastern Time. To get to know the audience a bit better, please fill out this brief survey to register. Those who register will receive a meeting invite with a link to the Zoom room.

What is a Dialogue?

The Science of Community Dialogue Series is a series of conversations among researchers, experts, community organizers, and others interested in how communities work, collaborate, and succeed. To learn more, watch this short introduction video with Aaron Shaw.

Founders’ influence on their new online communities

Hundreds of new subreddits are created every day, but most of them go nowhere, and never receive more than a few posts or comments. On the other hand, some become wildly popular. If we want to figure out what helps some things to get attention, then looking at new and small online communities is a great place to start. Indeed, the whole focus of my dissertation was trying to understand who started new communities, and why. So, I was super excited when Sanjay Kairam at Reddit told me that Reddit was interested in studying founders of new subreddits!

The research that Sanjay and I (but mostly Sanjay!) did was accepted at CHI 2024, a leading conference for human-computer interaction research. The goal of the research is to understand 1) founders’ motivations for starting new subreddits, 2) founders’ goals for their communities, 3) founders’ plans for making their community successful, and 4) how all of these relate to what happens to a community in the first month of its existence. To figure this out, we surveyed nearly 1,000 redditors one week after they created a new subreddit.

Lots of Motivations and Goals

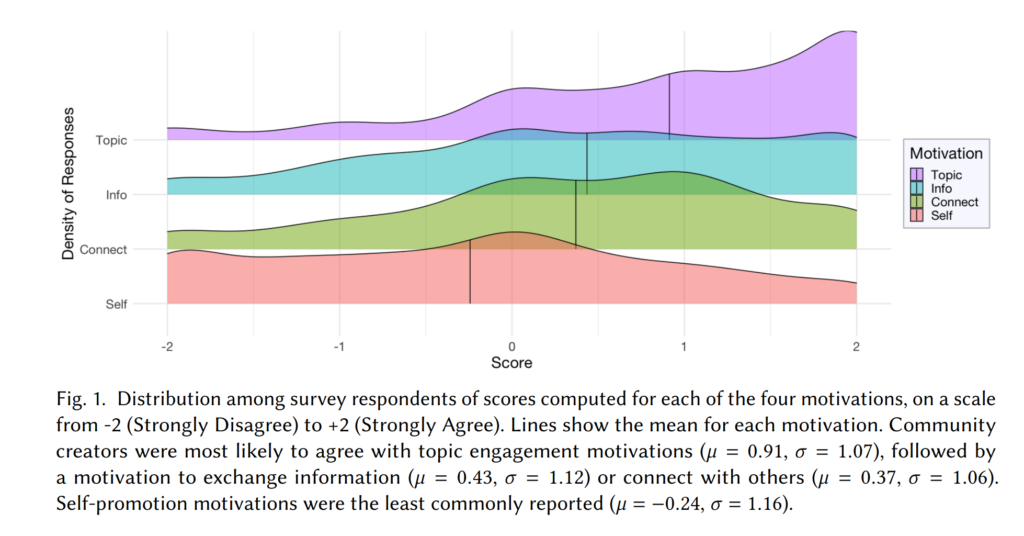
So, what did we learn? First, that founders have diverse motivations, but the most common is interest in the topic. As shown in the figure above, most founders reported being motivated by topic engagement, information exchange, and connecting with others, while self-promotion was much more rare.

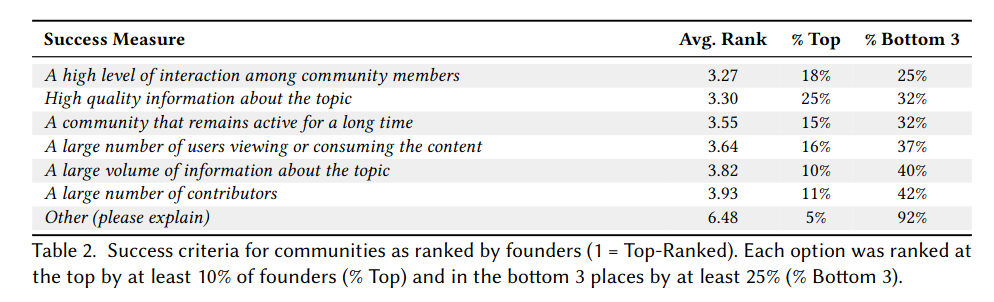
When we asked about their goals for the community, founders were split, and each of the options we gave was ranked as a top goal by a good chunk of participants. While there is some nuance between the different versions of success, we grouped them into “quantity-oriented” and “quality-oriented”, and looked at how motivations related to goals. Somewhat unsurprisingly, folks interested in self-promotion had quantity-oriented goals, while those interested in exchanging information were more focused on quality.

Diversity in plans

We then asked founders about what plans they had for building their community, based on recommendations from the online community literature, such as raising awareness, welcoming newcomers, encouraging contributions, and regulating bad behavior. Surprisingly, for each activity, about half of people said they planned to engage in doing that thing.

Early Community Outcomes

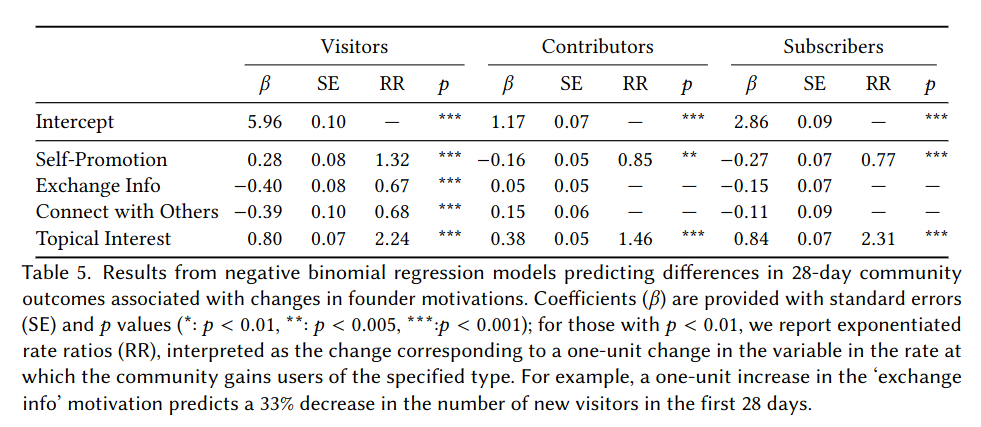
So, how do these motivations, goals, and plans relate to community outcomes? We looked at the first 28 days of each founded subreddit, and counted the number of visitors, number of contributors, and number of subscribers. We then ran regression analyses analyzing how well each aspect of motivations, goals, and plans predicted each outcome. High-level results and regression tables are shown below. For each row, when β is positive, that means that the given feature has a positive relationship with the given outcome. The exponentiated rate ratio (RR) column provides a point estimate of the effect size. For example, Self-Promotion has an RR of 1.32, meaning that if a given person’s self-promotion motivation was one unit higher the model predicts that their community would receive 32% more visitors.

A number of motivations predicted each of the outcomes we measured. The only consistently positive predictor was topical interest. Those who started a community because of interest in a topic had more visitors, more contributors, and more subscribers than others. Interestingly, those motivated by self-promotion had more visitors, but fewer contributors and subscribers.

Goals had a less pronounced relationship with outcomes. Those with quality-oriented goals had more contributors but fewer visitors than those with quantity-oriented goals. There was no significant difference in subscribers for founders with different types of goals.

Finally, raising awareness was the strategy most associated with our success metrics, predicting all three of them. Surprisingly, encouraging contributions was associated with more contributors, but fewer visitors. While we don’t know the mechanism for sure, asking for contributions seems to provide a barrier that discourages newcomers from taking interest in a community.

So what?

We think that there are some key takeaways for platform designers and those starting new communities. Sanjay outlined many of them on the Reddit engineering blog, but I’ll recap a few.

First, topical knowledge and passion is important. This isn’t a causal study, so we don’t know the mechanisms for sure, but people who are passionate about a topic may be aware of other communities in the space and are able to find the right niche; they are also probably better at writing the kinds of welcome messages, initial posts, etc. that appeal to people interested in the topic.

Second, our work is yet more evidence that communities require different things at different points in their lifecycle. Founders should probably focus on building awareness at first, and worry less about encouraging contributions or regulating behavior.

Finally, we think there are a lot of opportunities for designers to take diverse motivations and goals seriously. This could include matching people by their motivations for using a community, developing dashboards that capture different aspects of success and community health and quality, etc.

Learn More

If you want to learn more about the paper, you have options!

Join us! Call for Ph.D. Applications and Public Q&A Event

It’s Ph.D. application season and the Community Data Science Collective is recruiting! As always, we are looking for talented people to join our research group. Applying to one of the Ph.D. programs that the CDSC faculty members are affiliated with is a great way to get involved in research on communities, collaboration, and peer production.

Because we know that you may have questions for us that are not answered in this webpage, we will be hosting an open house and Q&A about the CDSC and Ph.D. opportunities on Friday, October 20 at 18:00 UTC (2:00pm US Eastern, 1:00pm US Central, 11:00am US Pacific). You can register online.

This post provides a very brief run-down on the CDSC, the different universities and Ph.D. programs our faculty members are affiliated with, and some general ideas about what we’re looking for when we review Ph.D. applications.

Group photo of the collective at a recent retreat.

What is the Community Data Science Collective?

The Community Data Science Collective (or CDSC) is a joint research group of (mostly quantitative) empirical social scientists and designers pursuing research about the organization of online communities, peer production, and learning and collaboration in social computing systems. We are based at Northwestern University, the University of Washington, Carleton College, Purdue University, and a few other places. You can read more about us and our work on our research group blog and on the collective’s website/wiki.

What are these different Ph.D. programs? Why would I choose one over the other?

This year the group includes three faculty principal investigators (PIs) who are actively recruiting PhD students: Aaron Shaw (Northwestern University), Benjamin Mako Hill (University of Washington in Seattle), and Jeremy Foote (Purdue University). Each of these PIs advise Ph.D. students in Ph.D. programs at their respective universities. Our programs are each described below.

Although we often work together on research and serve as co-advisors to students in each others’ projects, each faculty person has specific areas of expertise and interests. The reasons you might choose to apply to one Ph.D. program or to work with a specific faculty member could include factors like your previous training, career goals, and the alignment of your specific research interests with our respective skills.

At the same time, a great thing about the CDSC is that we all collaborate and regularly co-advise students across our respective campuses, so the choice to apply to or attend one program does not prevent you from accessing the expertise of our whole group. But please keep in mind that our different Ph.D. programs have different application deadlines, requirements, and procedures!

Faculty who are actively recruiting this year

If you are interested in applying to any of the programs, we strongly encourage you to reach out the specific faculty in that program before submitting an application.

Ph.D. Advisors

A photo of Jeremy Foote. He is wearing a grey shirt.
Jeremy Foote

Jeremy Foote is an Assistant Professor at the Brian Lamb School of Communication at Purdue University. He is affiliated with the Organizational Communication and Media, Technology, and Society programs. Jeremy’s research focuses on how individuals decide when and in what ways to contribute to online communities, how communities change the people who participate in them, and how both of those processes can help us to understand which things become popular and influential. Most of his research is done using data science methods and agent-based simulations.

A photo of Benjamin mako Hill. He is wearing a pink shirt.
Benjamin Mako Hill

Benjamin Mako Hill is an Associate Professor of Communication at the University of Washington. He is also adjunct faculty at UW’s Department of Human-Centered Design and Engineering (HCDE), Computer Science and Engineering (CSE) and Information School. Although many of Mako’s students are in the Department of Communication, he has also advised students in all three other departments—although he typically has more limited ability to admit students into those programs on his own and usually does so with a co-advisor in those departments. Mako’s research focuses on population-level studies of peer production projects, computational social science, efforts to democratize data science, and informal learning. Mako has also put together a webpage for prospective graduate students with some useful links and information..

A photo of Aaron Shaw. He is wearing a black shirt.
Aaron Shaw. (Photo credit: Nikki Ritcher Photography, cc-by-sa)

Aaron Shaw is an Associate Professor in the Department of Communication Studies at Northwestern. In terms of Ph.D. programs, Aaron’s primary affiliations are with the Media, Technology and Society (MTS) and the Technology and Social Behavior (TSB) Ph.D. programs (please note: the TSB program is a joint degree between Communication and Computer Science). Aaron also has a courtesy appointment in the Sociology Department at Northwestern, but he has not directly supervised any Ph.D. advisees in that department (yet). Aaron’s current projects focus on comparative analysis of the organization of peer production communities and social computing projects, participation inequalities in online communities, and collaborative organizing in pursuit of public goods.

What do you look for in Ph.D. applicants?

There’s no easy or singular answer to this. In general, we look for curious, intelligent people driven to develop original research projects that advance scientific and practical understanding of topics that intersect with any of our collective research interests.

To get an idea of the interests and experiences present in the group, read our respective bios and CVs (follow the links above to our personal websites). Specific skills that we and our students tend to use on a regular basis include consuming and producing social science and/or social computing (human-computer interaction) research; applied statistics and statistical computing, various empirical research methods, social theory and cultural studies, and more.

Formal qualifications that speak to similar skills and show up in your resume, transcripts, or work history are great, but we are much more interested in your capacity to learn, think, write, analyze, and/or code effectively than in your credentials, test scores, grades, or previous affiliations. It’s graduate school and we do not expect you to show up knowing how to do all the things already.

Intellectual creativity, persistence, and a willingness to acquire new skills and problem-solve matter a lot. We think doctoral education is less about executing tasks that someone else hands you and more about learning how to identify a new, important problem; develop an appropriate approach to solving it; and explain all of the above and why it matters so that other people can learn from you in the future. Evidence that you can or at least want to do these things is critical. Indications that you can also play well with others and would make a generous, friendly colleague are really important too.

All of this is to say, we do not have any one trait or skill set we look for in prospective students. We strive to be inclusive along every possible dimension. Each person who has joined our group has contributed unique skills and experiences as well as their own personal interests. We want our future students and colleagues to do the same.

Now what?

Still not sure whether or how your interests might fit with the group? Still have questions? Still reading and just don’t want to stop? Follow the links above for more information. Feel free to send at least one of us an email. We are happy to try to answer your questions and always eager to chat. You can also join our open house on October 20 at 2:00pm ET (UTC-4).
The social structure of new wiki communities

A new paper that our that our group has published seeks to test whether the kind of communication patterns associated with successful offline teams also predict success in online collaborative settings. Surprisingly, we find that it does not. In the rest of this blog post, we summarize that research and unpack that result.

Many of us have been part of a work team where everyone clicked. Everyone liked and respected each other, maybe you even hung out together outside of work. In a team like that, when someone asks you to cover a shift, or asks you to stay late to help them finish a project, you do it.

This anecdotal experience that many of us have is borne out by research. When members of work groups in corporate settings feel integrated into a group, and particularly when their identity is connected to their group membership, they are more willing to contribute to the group’s goals. Integrative groups (where there isn’t a strong hierarchy and where very few people are on the periphery) are also able to communicate and coordinate their work better.

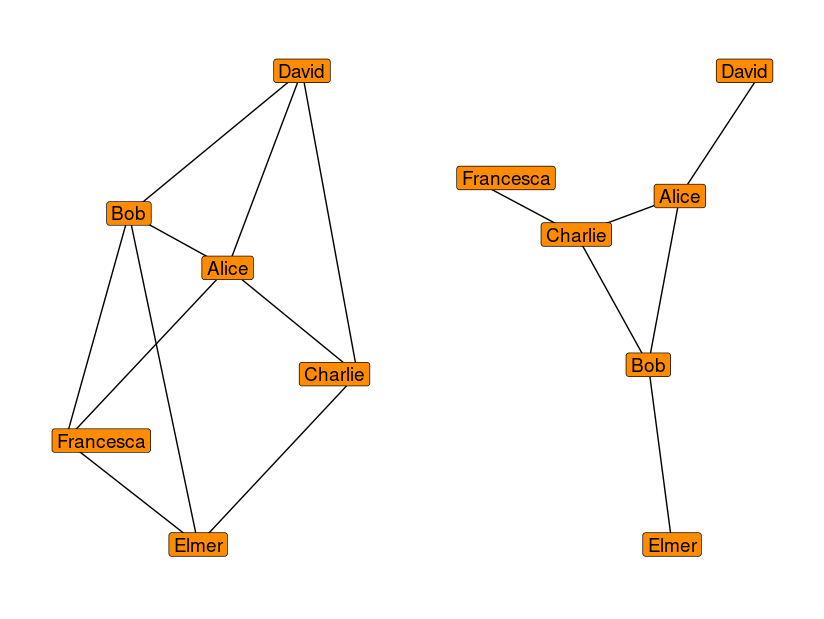
One way to measure whether a group is “integrative” is to look at the group’s conversation networks, as shown in the figure below. Groups where few people are on the periphery (like on the left) usually perform better along a number of dimensions, such as creativity and productivity.

Examples of two possible configurations of a work group. The work group on the left is much more “integrative,” and we would expect it to be more creative and productive.

In our new paper, we set out to look for evidence that early online wiki communities at Fandom.com work the same way as work groups. When communities are getting started, there are lots of reasons to think that they would also benefit from integrative networks. Their members typically don’t know each other and communicate mostly via text—conditions that should make building a shared identity tough. In addition, they are volunteers who can easily leave at any time. The research on work groups made us think that integrative social structures would be especially important in making new wikis successful.

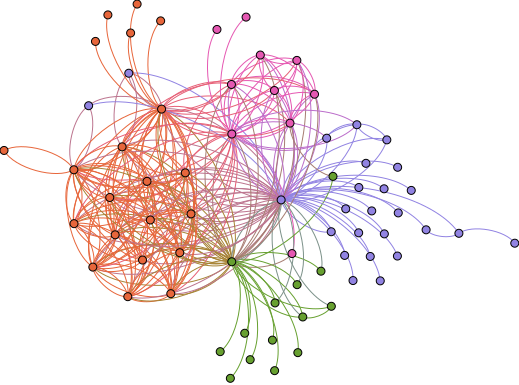
Communication network of the Spongebob wiki after 700 edits

In order to measure the social structure of these communities, we created communication networks for almost 1,000 wikis for the talk that happened during their firs 700 main page edits. Connections between people were based on who talked to whom on Talk pages. These are wiki pages connected to each page and each registered user on a wiki. We connected users who talked to each other at least a few times on the same talk pages, and looked at whether how integrative a communication network was predicted 1) how much people contributed and 2) how long a wiki remained active.

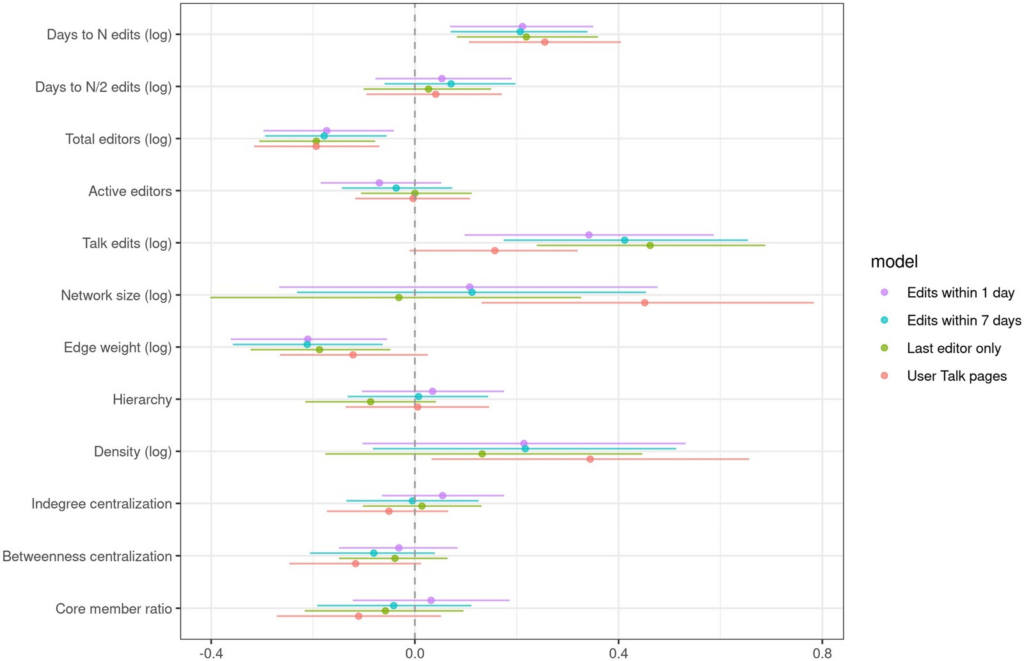
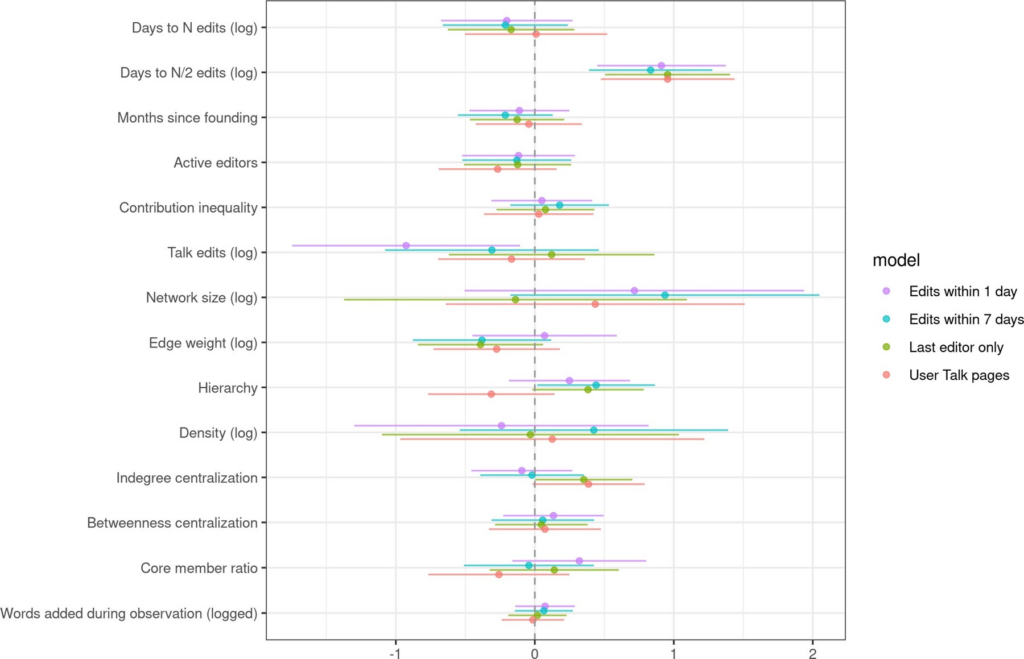
Surprisingly, we found that no matter how we measured communication networks, and no matter how we measured success, integrative network measures were not good at predicting that a wiki would survive or be productive. While a few of our control variables helped to predict productivity and survival, none of the network measures (nor all of them taken together) helped much to predict either of our success measures, as shown in Figures 5 and 6 from the paper.

Figure 5. Estimated coefficients predicting the productivity of a wiki.
Figure 6. Estimated coefficients predicting how quickly a wiki will become inactive.

So, what is going on here?

We have a few possible explanations for why communication network structures don’t seem to matter. One is that group identity for wiki members may not be influenced much by network structure. In a work group, it can be painfully obvious if you are on the periphery and not included in conversations or activities. Even though wiki conversations are technically all public and visible, in practice it’s very easy for group members to be unaware of conversations happening in other parts of the site. This idea is supported by research led by Sohyeon Hwang, which showed that people can build identity in an online community even without personal relationships.

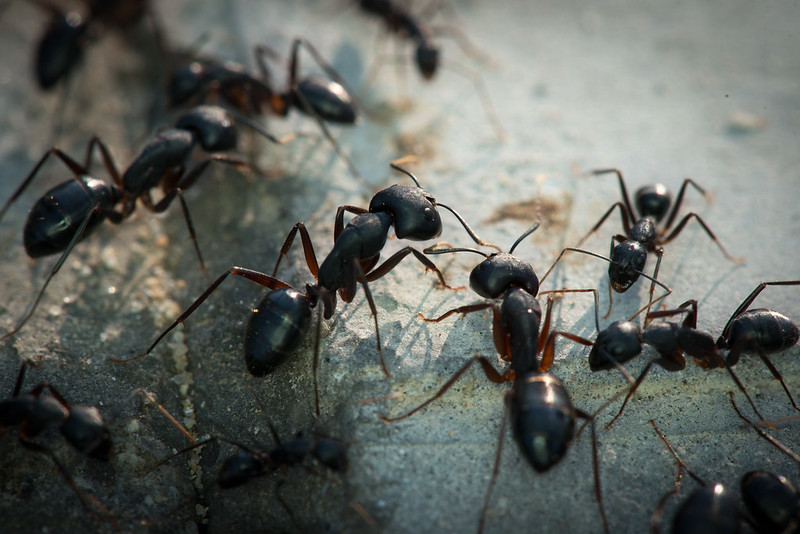
Another complementary explanation for how groups coordinate work without integrative communication networks is that wiki software helps to organize what needs to be done without explicit communication. Much of this happens just because the central artifact of the community—the wiki—is continuously updated, so it is (relatively) clear what has been done and what needs to be done. In addition, there are opportunities for stigmergy. Stigmergy occurs when actors modifying the environment as a way of communicating. Then, others make decisions based on observing the environment. The canonical example is ants who leave pheremone trails for other ants to find and follow.

In wikis, this can be accomplished in a few ways. For example, contributors can create a link to a page that doesn’t yet exist. By default, these show up as red links, suggesting to others that a page needs to be created.

A final possible explanation for our results is based on how easy it is to join and leave online communities. It may be that integrative structures are so important because they help groups to overcome and navigate conflicts; in online communities contributors may be more likely to simply disengage instead of trying to resolve a conflict.

As we conclude in the paper:

Why do communication networks—important predictors of group performance outcomes across diverse domains—not predict productivity or survival in peer production? Our findings suggest that the relationship of communication structure to effective collaboration and organization is not universal but contingent. While all groups require coordination and undergo social influence, groups composed of different types of people or working in different technological contexts may have different communicative needs. Wikis provide a context where coordination via stigmergy may suffice and where the role of cheap exit as well as the difficulty of group-level conversation may lead to consensus-by-attrition.

We hope that others will help us to study some of these mechanisms more directly, and look forward to talking more with researchers and others interested in how and why online groups succeed.


The full citation for the paper is: Foote, Jeremy, Aaron Shaw, and Benjamin Mako Hill. 2023. “Communication Networks Do Not Predict Success in Attempts at Peer Production.” Journal of Computer-Mediated Communication 28 (3): zmad002. https://doi.org/10.1093/jcmc/zmad002.

We have also released replication materials for the paper, including all the data and code used to conduct the analyses.

A systems approach to studying online communities

Systems theory is a broad and multidisciplinary scientific approach that studies how things (molecules or cells or organs or people or companies) interact with each other. It argues that understanding how something works requires understanding its relationships and interdependencies.

For example, if we want to predict whether a new online community will grow, an individual perspective might focus on who the founder is, what software it is running on, how well it is designed, etc. A systems approach would argue that it is at least as important to understand things like how many similar communities there are, how active they are, and whether the platform is growing or shrinking.

In a paper just published in Media and Communication, I (Jeremy) argue that 1) it is particularly important to use a systems lens to study online communities, 2) that online communities provide ideal data for taking these approaches, and 3) that there is already really neat research in this area and there should be more of it.

The role of platforms

So, why is it so important to study online communities as interdependent “systems”? The first reason is that many online communities have a really important interdependence with the platforms that they run on. Platforms like Reddit or Facebook provide the servers and software for millions of communities, which are run mostly independently by the community managers and moderators.

However, this is an ambivalent relationship and often the goals and desires of at least some moderators are at odds with those of the platform, and things like community bans from the platform side or protests from the community side are not uncommon. The ways that platform decisions influence communities and how communities can work together to influence platforms are inherently systems questions.

Low barriers to entry and exit

A second feature of online communities is the relative ease with which people can join or leave them. Unlike offline groups, which at least require participants to get dressed, do their hair, and show up somewhere, online community participants can participate in an online community literally within seconds of knowing that it exists.

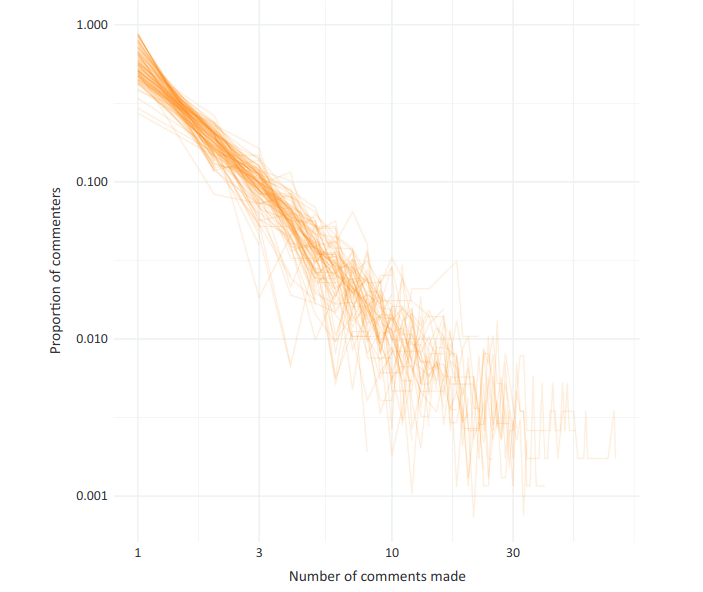
Similarly, people can leave incredibly easily, and most people do. This figure shows the number of comments made per person across 100 randomly selected subreddits (each line represents a subreddit; axes are both log-scaled). In every case, the vast majority of people only commented once while a few people made many comments.

Fuzzy boundaries

Finally, it’s often really difficult to draw clear boundaries around where one online community ends and another begins. For example, is all of Wikipedia one “community”? It might make sense to think of a language edition, a WikiProject, or even a single page as a community, and researchers have done all of the above. Even on platforms like Reddit, where there is a clearl delineation between communities, there are dependencies, with people and conversations moving across and between communities on similar topics.

In other words, online communities are semi-autonomous, interdependent, contingent organizations, deeply influenced by their environments. Online community scholars have often ignored this larger context, but systems theory gives us a rich set of tools for studying these interdependencies. One reason that it is so ideal is because online communities provide ideal data.

Data from Online Communities

Systems theory is not new – many of the main concepts were developed in the 1950s and 1960s or earlier. Organizational communication researchers saw how applicable these ideas were, and many researchers proposed treating organizations as systems.

However, it was really tough to get the data needed to do systems-based research. To study a group or organization as a system, you need to know about not only the internal workings of the group, but how it relates to other groups, how it is influenced by and influences its environment, etc. Gathering data about even one group was difficult and expensive; getting the data to study many groups and how they interact with each other over time was impossible.

The internet has entered the chat

Online communities provide the kind of data that these earlier researchers could have only dreamed of. Instead of data about one organization, platforms store data about thousands of organizations. And this is not just high-level data about activity levels or participation; on the contrary, we often have longitudinal, full-text conversations of millions of people as they interact within and move between communities.

Systems Approaches

In part, this article is a call for researchers to think more explicitly about online communities as systems, and to apply systems theory as a way of understanding how online communities work and how we can design research projects to understand them better. It is also an attempt to highlight strands of research that are already doing this. In the paper, I talk about four: Community Comparisons and Interactions, Individual Trajectories, Cross-level Mechanisms, and Simulating Emergent Behavior. Here, I’ll focus on just two.

Individual Trajectories

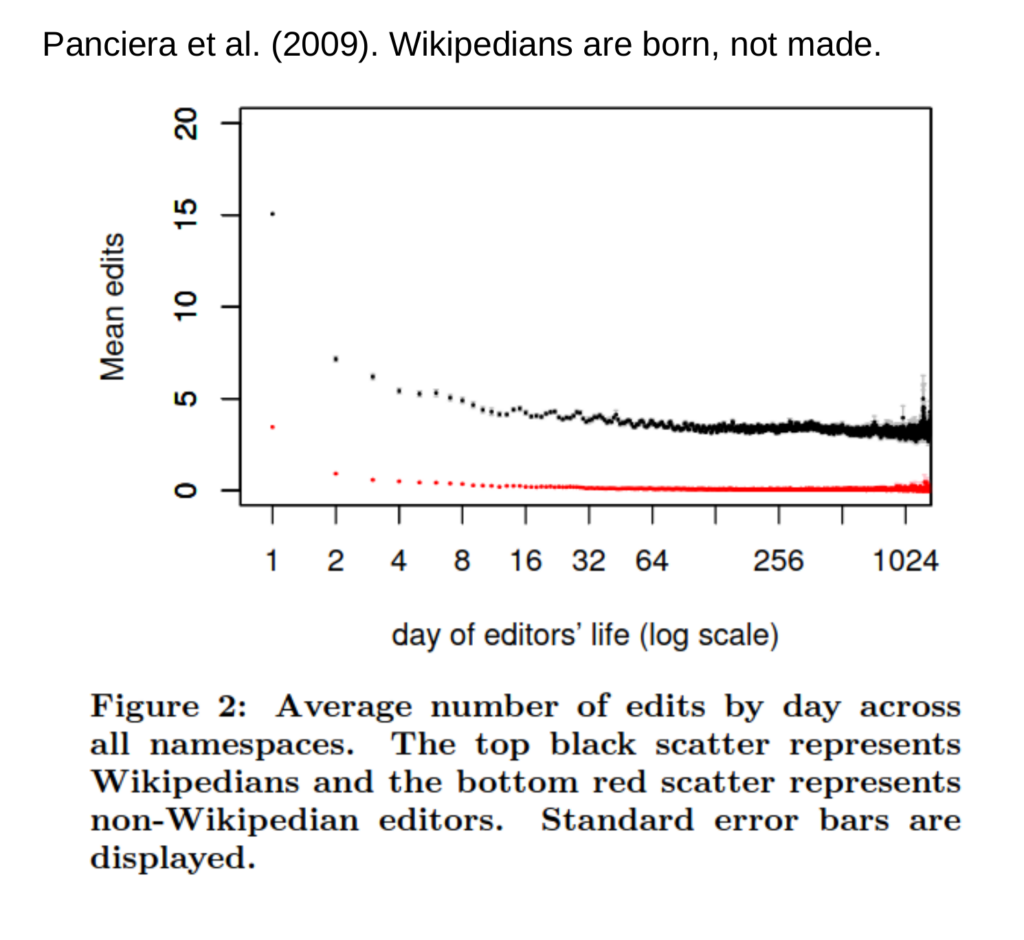
Figure from Panciera, K., Halfaker, A., & Terveen, L. (2009). Wikipedians are born, not made: A study of power editors on Wikipedia. Proceedings of the ACM 2009 International Conference on Supporting Group Work, 51–60. https://doi.org/10.1145/1531674.1531682

The first is what I call “Individual Trajectories”. In this approach, researchers can look at how individual people behave across a platform. One of the neat things about having longitudinal, unobtrusively collected data is that we can identify something interesting about users and go “back in time” to look for differences in earlier behavior. For example, in the plot above, Panciera et al. identified people who became active Wikipedia editors; they then went back and looked at how their behavior differed from typical editors from their early days on the site.

Researchers could and should do more work that looks at how people move between communities, and how communities influence the behavior of their members.

Simulating Emergent Behavior

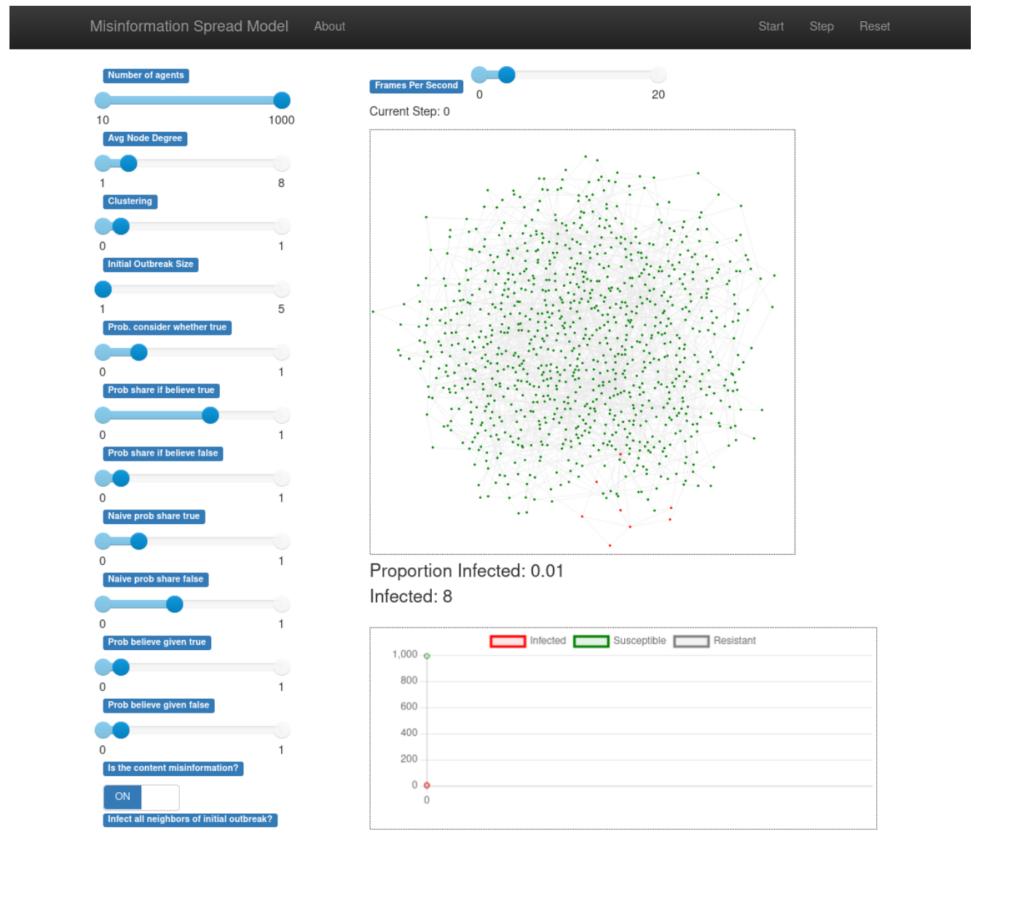
The second approach is to use simulations to study emergent behaviors. Agent-based modeling software like NetLogo or Mesa allows researchers to create virtual worlds, where computational “agents” act according to theories of how the world works. Many communication theories make predictions about how individual‐level behavior produces higher‐level patterns, often through feedback loops (e.g., the Spiral of Silence theory). If agent-based models don’t produce those patterns, then we know that something about the theory—or its computational representation—is wrong.

Model of misinformation spread, from Hu et al. (under review)

Agent-based modeling has received some attention from communication researchers lately, including a wonderful special issue was recently published in Communication Methods and Measures; the editorial article makes some great arguments for the promise and benefits of simulations for communication research.

New Opportunities

It is a really exciting time to be a computational social scientist, especially one that is interested in online organizations and organizing. We have only scratched the surface of what we can learn from the data that is pouring down around us, especially when it comes to systems theory questions. Tools, methods, and computational advances are constantly evolving and opening up new avenues of research.

Of course, taking advantage of these data sources and computational advances requires a different set of skills than Communication departments have traditionally focused on, and complicated, large-scale analyses require the use of supercomputers and extensive computational expertise.

However, there are many approaches like agent-based modeling or simple web scraping that can be taught to graduate students in one or two semesters, and open up lots of possibilities for doing this kind of research.

I’d love to talk more about these ideas—please reach out, or if you are coming to ICA, come talk to me!

Forming, storming, norming, performing, and …chloroforming?

In 1965, Bruce Tuckman proposed a “developmental sequence in small groups.” According to his influential theory, most successful groups go through four stages with rhyming names:

  1. Forming: Group members get to know each other and define their task.
  2. Storming: Through argument and disagreement, power dynamics emerge and are negotiated.
  3. Norming: After conflict, groups seek to avoid conflict and focus on cooperation and setting norms for acceptable behavior.
  4. Performing: There is both cooperation and productive dissent as the team performs the task at a high level.

Fortunately for organizational science, 1965 was hardly the last stage of development for Tuckman’s theory!

Twelve years later, Tuckman suggested that adjourning or mourning reflected potential fifth stages (Tuckman and Jensen 1977). Since then, other organizational researchers have suggested other stages including transforming and reforming (White 2009), re-norming (Biggs), and outperforming (Rickards and Moger 2002).

What does the future hold for this line of research?

To help answer this question, we wrote a regular expression to identify candidate words and placed the full list is at this page in the Community Data Science Collective wiki.

The good news is that despite the active stream of research producing new stages that end or rhyme with -orming, there are tons of great words left!

For example, stages in a group’s development might include:

  • Scorning: In this stage, group members begin mocking each other!
  • Misinforming: Groups that reach this stage start producing fake news.
  • Shoehorning: These groups try to make their products fit into ridiculous constraints.
  • Chloroforming: Groups become languid and fatigued?

One benefit of keeping our list in the wiki is that the organizational research community can use it to coordinate! If you are planning to use one of these terms—or if you know of a paper that has—feel free to edit the page in our wiki to “claim” it!


Although credit for this post goes primarily to Jeremy Foote and Benjamin Mako Hill, the other Community Data Science Collective members can’t really be called blameless in the matter either.

Summer Institute in Computational Social Science

For the second year, Matt Salganik and Chris Bail are running a two-week Summer Institute in Computational Social Science at Duke Univeristy. The goal of the institute is to bring social scientists and data scientists together to learn about computational social science, which can be described as a merger of their two fields.

This year, there are seven partner locations where local students livestream the activities from Duke and learn from local computational social scientists.  Both of our universities are among the partner locations.

At the University of Washington, Kaylea and Charlie have both been accepted as participants in the UW summer institute. At Northwestern University, Jeremy is helping to organize SICSS Chicago.

Much of the work that we do in the Community Data Science Collective could be considered computational social science, and we are excited about the potential for  computational methods in social science. This is a great program for helping to disseminate computational social science approaches and train the next generation of computational social scientists. The Community Data Science Collective is happy to be a sponsor of the Chicago partner location.

Introducing Computational Methods to Social Media Scientists

The ubiquity of large-scale data and improvements in computational hardware and algorithms have provided enabled researchers to apply computational approaches to the study of human behavior. One of the richest contexts for this kind of work is social media datasets like Facebook, Twitter, and Reddit.

We were invited by Jean Burgess, Alice Marwick, and Thomas Poell to write a chapter about computational methods for the Sage Handbook of Social Media. Rather than simply listing what sorts of computational research has been done with social media data, we decided to use the chapter to both introduce a few computational methods and to use those methods in order to analyze the field of social media research.

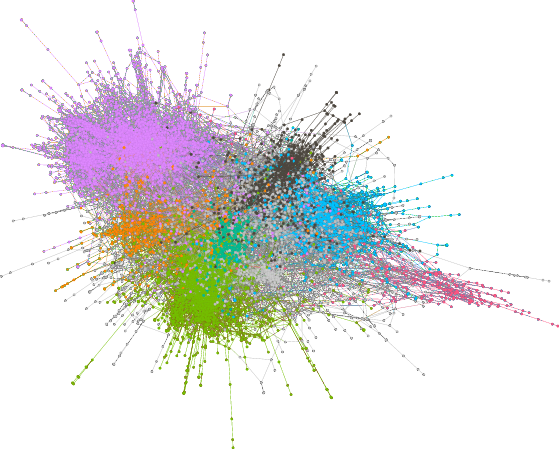
A “hairball” diagram from the chapter illustrating how research on social media clusters into distinct citation network neighborhoods.

Explanations and Examples

In the chapter, we start by describing the process of obtaining data from web APIs and use as a case study our process for obtaining bibliographic data about social media publications from Elsevier’s Scopus API.  We follow this same strategy in discussing social network analysis, topic modeling, and prediction. For each, we discuss some of the benefits and drawbacks of the approach and then provide an example analysis using the bibliographic data.

We think that our analyses provide some interesting insight into the emerging field of social media research. For example, we found that social network analysis and computer science drove much of the early research, while recently consumer analysis and health research have become more prominent.

More importantly though, we hope that the chapter provides an accessible introduction to computational social science and encourages more social scientists to incorporate computational methods in their work, either by gaining computational skills themselves or by partnering with more technical colleagues. While there are dangers and downsides (some of which we discuss in the chapter), we see the use of computational tools as one of the most important and exciting developments in the social sciences.

Steal this paper!

One of the great benefits of computational methods is their transparency and their reproducibility. The entire process—from data collection to data processing to data analysis—can often be made accessible to others. This has both scientific benefits and pedagogical benefits.

To aid in the training of new computational social scientists, and as an example of the benefits of transparency, we worked to make our chapter pedagogically reproducible. We have created a permanent website for the chapter at https://communitydata.science/social-media-chapter/ and uploaded all the code, data, and material we used to produce the paper itself to an archive in the Harvard Dataverse.

Through our website, you can download all of the raw data that we used to create the paper, together with code and instructions for how to obtain, clean, process, and analyze the data. Our website walks through what we have found to be an efficient and useful workflow for doing computational research on large datasets. This workflow even includes the paper itself, which is written using LaTeX + knitr. These tools let changes to data or code propagate through the entire workflow and be reflected automatically in the paper itself.

If you  use our chapter for teaching about computational methods—or if you find bugs or errors in our work—please let us know! We want this chapter to be a useful resource, will happily consider any changes, and have even created a git repository to help with managing these changes!

Introduction to R workshop

I recently taught a two-session workshop introducing R to Kellogg MBA students. I had  a few goals for the workshops:

  1. Convince students of the benefits of using text-based programming for data exploration and analysis
  2. Introduce basic programming concepts (e.g., variables, functions)
  3. Give students a basic understanding of how to do some fundamental data analysis tasks in R: importing, cleaning, visualizing, and modeling

Those are really big goals for only four hours. I decided to use the tidyverse as much as possible and not even teach base R syntax like ‘[,]’, apply, etc. I used the first session to show and explain code using the nycflights13 dataset. For the the second session we did a few more examples but mostly worked on exercises using a dataset from Wikia that I created (with help from Mako and Aaron Halfaker‘s code and data).

Learning R does have its downsides

Retrospection

Overall, I think that the workshops went pretty well. I think that students definitely have a better understanding and a better set of tools than I did after I had used R for four hours!

That being said, there was plenty of room for improvement. I am scheduled to teach another set of workshops early next year and I’m planning to make a few changes:

  1. Make both of the workshops more hands-on and interactive. I think I’ll divide the topics covered: the first workshop will be on importing, cleaning, and grouping data and the second will be on visualizing and creating inferential models.
  2. Get more help – teaching non-programmers R requires some hand-holding and individual attention. To be successful, I think a workshop like this requires 1 “TA” for every 8-10 students.
  3. Find a more relevant dataset. Although I actually learned a few things about my dataset that will help with my papers that use it, I think it would be better to have a dataset that is as similar as possible to what students will be working with in their careers.
  4. Connect the visualization and regression more directly to a specific analysis problem rather than as syntax-learning exercises.

Reuse this workshop!

I found some pretty good resources already in existence for introducing students to R, but none of them quite fit the scope of what I was looking for.  All of the code that I used (as well as some slides for the beginning of class) are on github and GPL licensed. Please reuse my work and submit pull requests!